Join our WeChat and Discord community Use GLM-OCR's API GLM-OCR is a multimodal OCR model for complex document understanding, built on the GLM-V encoder–decoder architecture. It introduces Multi-Token Prediction (MTP) loss and stable full-task reinforcement learning to improve training efficiency, recognition accuracy, and generalization. The model integrates the CogViT visual encoder pre-trained on large-scale image–text data, a lightweight cross-modal connector with efficient token downsampling, and a GLM-0.5B language decoder. Combined with a two-stage pipeline of layout analysis and parallel recognition based on PP-DocLayout-V3, GLM-OCR delivers robust and high-quality OCR performance…

kosmos-2-patch14-224 is an open-weight model for image to text from Microsoft, released under MIT License. It has 1.7B parameters and a 2,048-token context. At 16-bit it needs about 4 GB of GPU memory, which fits on 1x MI300X from $1.85 an hour, at the lowest prices in the SAVRN Index. It draws 139.9k downloads a month.
This Hub repository contains a HuggingFace's transformers implementation of the original Kosmos-2 model from Microsoft. Use the code below to get started with the model. This model is capable of performing different tasks through changing the prompts.
Parameters1.7B
Context2,048
Weights13.3 GB
Licensemit
AccessOpen weights
Monthly Downloads139.9k
Runs On
What it takes to serve kosmos-2-patch14-224 (1.7B parameters): the memory its weights need at each precision, and the cheapest way to rent enough data-center GPUs to hold them.
| Precision | Weights | Memory needed | Cheapest setup | Per hour | Also fits |
|---|---|---|---|---|---|
| 16-bit | 3.3 GB | 4.0 GB | 1x MI300X (192 GB) Vultr |
$1.85 | 1x H100 $1.99 · 1x MI325X $2.00 |
| 8-bit | 1.7 GB | 2.0 GB | 1x MI300X (192 GB) Vultr |
$1.85 | 1x H100 $1.99 · 1x MI325X $2.00 |
| 4-bit | 0.8 GB | 1.0 GB | 1x MI300X (192 GB) Vultr |
$1.85 | 1x H100 $1.99 · 1x MI325X $2.00 |
Memory is the weights at that precision plus 20% for the runtime and a short context; a long context needs more. Prices are the lowest on-demand hourly rates in the SAVRN Index, read Oct 16, 2026.
kosmos-2-patch14-224 on every accelerator the SAVRN Index prices, at every precision
Model Card
By Microsoft, published under mit, revision e91cfbcb4ce0.
Kosmos-2: Grounding Multimodal Large Language Models to the World
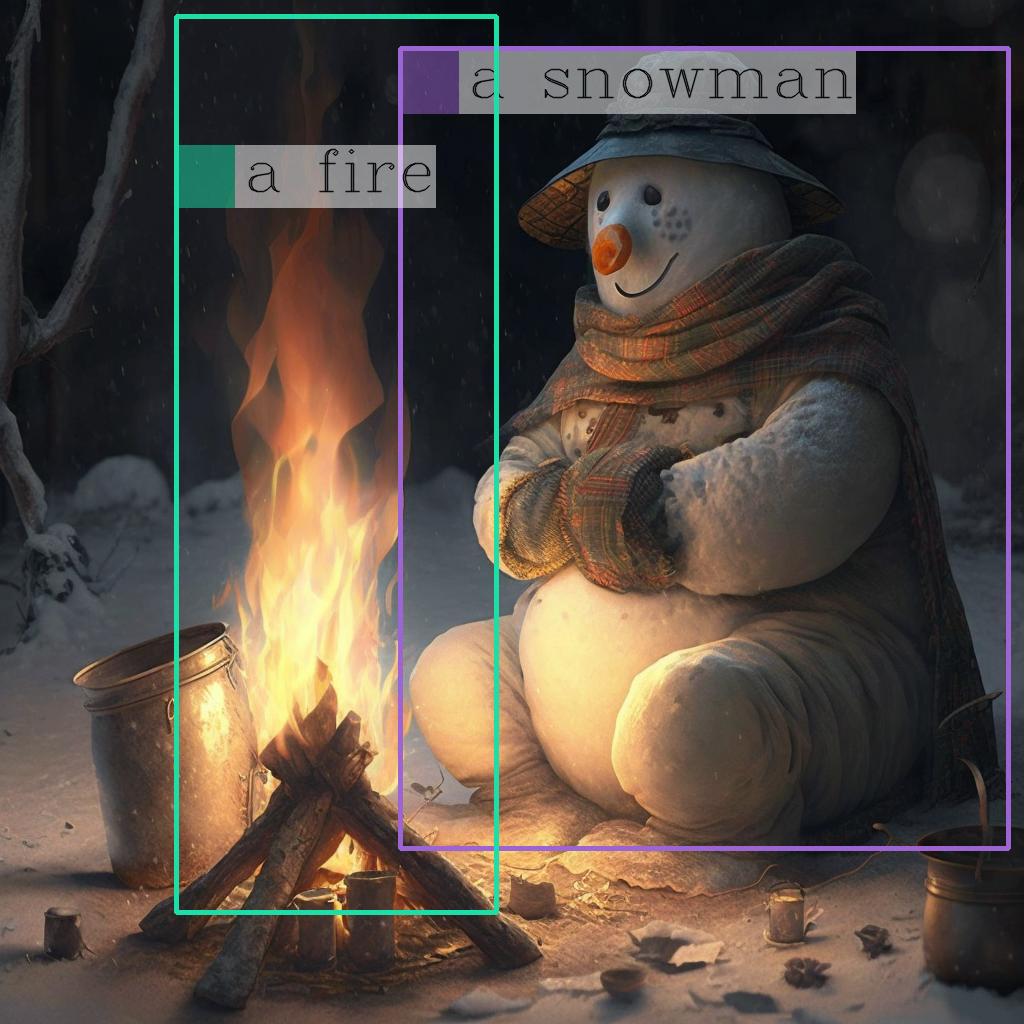
[An image of a snowman warming himself by a fire.]
This Hub repository contains a HuggingFace's transformers implementation of the original Kosmos-2 model from Microsoft.
How to Get Started with the Model
Use the code below to get started with the model.
Configuration
- Architecture
- Kosmos2ForConditionalGeneration
- Context length (tokens)
- 2,048
- Vocabulary size
- 65,037
- Stored precision
- float32
- Model type
- kosmos-2
Identity and Version
- Repository
- microsoft/kosmos-2-patch14-224
- Publisher
- Microsoft
- Task
- Image to text
- Modality
- Image and text
- Library
- transformers
- Parameters
- 1.7B parameters
- Languages
- Not stated by the source
- Revision
- e91cfbcb4ce051b6a55bfb5f96165a3bbf5eb82c
- First published
- 2023-10-02
- Last updated
- 2023-11-28
Files and Weights
16 files, 13.3 GB in total. The weights are 2 files totalling 13.3 GB in bin, safetensors.
Weights2 files · 13.3 GB
Configuration5 files · 38.2 KB
Tokenizer2 files · 4.9 MB
Documentation1 file · 15.8 KB
Other5 files · 3.0 MB
Repository1 file · 1.6 KB
Every file
| File | Type | Size | SHA-256 |
|---|---|---|---|
| model.safetensors | Weights | 6.7 GB | 051bf4b62a25 |
| pytorch_model.bin | Weights | 6.7 GB | 47e771fe58dd |
| added_tokens.json | Configuration | 32.0 KB | — |
| config.json | Configuration | 4.5 KB | — |
| generation_config.json | Configuration | 137 B | — |
| preprocessor_config.json | Configuration | 534 B | — |
| special_tokens_map.json | Configuration | 1.1 KB | — |
| README.md | Documentation | 15.8 KB | — |
| annotated_snowman.jpg | Other | 124.0 KB | — |
| sentencepiece.bpe.model | Other | 1.4 MB | 3a60b4d1d1d8 |
| snowman.jpg | Other | 103.6 KB | — |
| snowman.png | Other | 1.4 MB | b97825997df0 |
| two_dogs.jpg | Other | 80.0 KB | — |
| .gitattributes | Repository | 1.6 KB | — |
| tokenizer.json | Tokenizer | 4.7 MB | — |
| tokenizer_config.json | Tokenizer | 190.7 KB | — |
License and Download
- License
- mit
- Access
- Open weights, no gate
- Download size
- 13.3 GB
Download from Microsoft
Released by Microsoft through its official repository on Hugging Face. Read the license.
Memory Requirements
| Precision | Weights in memory |
|---|---|
| As published | 13.3 GB |
| 16-bit | 3.3 GB |
| 8-bit | 1.7 GB |
| 4-bit | 0.8 GB |
Weights only, from the published parameter count; the key-value cache and runtime add to this.
Questions About kosmos-2-patch14-224
How much GPU memory does kosmos-2-patch14-224 need?
About 4 GB at 16-bit and 1 GB at 4-bit: the weights (1.7B parameters) plus a working margin. A long context needs more.
What is the cheapest GPU to run kosmos-2-patch14-224 on?
At 16-bit, 1x MI300X from $1.85 an hour; at 4-bit, 1x MI300X from $1.85 an hour, at the lowest on-demand prices the SAVRN Index lists.
Can I use kosmos-2-patch14-224 commercially?
Yes. kosmos-2-patch14-224 is released under MIT License. The MIT License is a short permissive license. It permits commercial use, modification and redistribution, provided the copyright notice and permission notice are included.
What is kosmos-2-patch14-224's context length?
2,048 tokens, from the maximum position embeddings in its published configuration.
Similar Models

Join our WeChat and Discord community Use GLM-OCR's API GLM-OCR is a multimodal OCR model for complex document understanding, built on the GLM-V encoder–decoder architecture. It introduces Multi-Token Prediction (MTP) loss and stable full-task reinforcement learning to improve training efficiency, recognition accuracy, and generalization. The model integrates the CogViT visual encoder pre-trained on large-scale image–text data, a lightweight cross-modal connector with efficient token downsampling, and a GLM-0.5B language decoder. Combined with a two-stage pipeline of layout analysis and parallel recognition based on PP-DocLayout-V3, GLM-OCR delivers robust and high-quality OCR performance…
Join our WeChat and Discord community Use GLM-OCR's API GLM-OCR is a multimodal OCR model for complex document understanding, built on the GLM-V encoder–decoder architecture. It introduces Multi-Token Prediction (MTP) loss and stable full-task reinforcement learning to improve training efficiency, recognition accuracy, and generalization. The model integrates the CogViT visual encoder pre-trained on large-scale image–text data, a lightweight cross-modal connector with efficient token downsampling, and a GLM-0.5B language decoder. Combined with a two-stage pipeline of layout analysis and parallel recognition based on PP-DocLayout-V3, GLM-OCR delivers robust and high-quality OCR performance…
Full BF16 version of the model. We recommend this variant for inference and further fine-tuning. LightOnOCR-1B is a compact, end-to-end vision–language model for Optical Character Recognition (OCR) and document understanding. It achieves state-of-the-art accuracy in its weight class while being several times faster and cheaper than larger general-purpose VLMs. Highlights LightOnOCR combines a Vision Transformer encoder(Pixtral-based) with a lightweight text decoder(Qwen3-based) distilled from high-quality open VLMs. It is optimized for document parsing tasks, producing accurate, layout-aware text extraction from high-resolution pages. All benchmarks evaluated using vLLM on the Olmo-Bench.…

This model was converted to MLX format from zai-org/GLM-OCR using mlx-vlm version 0.3.10. Refer to the original model card for more details on the model.
TrOCR model fine-tuned on the SROIE dataset. It was introduced in the paper TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models by Li et al. and first released in this repository. Disclaimer: The team releasing TrOCR did not write a model card for this model so this model card has been written by the Hugging Face team. The TrOCR model is an encoder-decoder model, consisting of an image Transformer as encoder, and a text Transformer as decoder. The image encoder was initialized from the weights of BEiT, while the text decoder was initialized from the weights of RoBERTa. Images are presented to the model as a sequence of fixed-size patches (resolution 16x16), which…