SAVRN
Search Contact SAVRN

Open-weight model · Text generation

Qwen3-VL-30B-A3B-Instruct-AWQ

by QuantTrio QuantTrio/Qwen3-VL-30B-A3B-Instruct-AWQ

As of 2025-10-08, create a fresh Python environment and run: For more details, refer to vLLM Official Qwen3-VL Guide Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date.

Parameters31.1B
Context262,144
Weights17.9 GB
Licenseapache-2.0
AccessOpen weights
Monthly Downloads1.2M

Runs On

What it takes to serve Qwen3-VL-30B-A3B-Instruct-AWQ (31.1B parameters): the memory its weights need at each precision, and the cheapest way to rent enough data-center GPUs to hold them.

PrecisionWeightsMemory neededCheapest setupPer hourAlso fits
16-bit 62.1 GB 74.6 GB 1x MI300X (192 GB)
Vultr
$1.85 1x H100 $1.99 · 1x MI325X $2.00
8-bit 31.1 GB 37.3 GB 1x MI300X (192 GB)
Vultr
$1.85 1x H100 $1.99 · 1x MI325X $2.00
4-bit 15.5 GB 18.6 GB 1x MI300X (192 GB)
Vultr
$1.85 1x H100 $1.99 · 1x MI325X $2.00

Memory is the weights at that precision plus 20% for the runtime and a short context; a long context needs more. Prices are the lowest on-demand hourly rates in the SAVRN Index, read Sep 18, 2026.

Model Card

By QuantTrio, published under apache-2.0, revision a5ea10732e2c.

As of 2025-10-08, create a fresh Python environment and run: For more details, refer to vLLM Official Qwen3-VL Guide Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date. This generation delivers comprehensive upgrades across the board: superior text understanding & generation, deeper visual perception & reasoning, extended context length, enhanced spatial and video dynamics comprehension, and stronger agent interaction capabilities. Available in Dense and MoE architectures that scale from edge to cloud, with Instruct and reasoning‑enhanced Thinking editions for flexible, on‑demand deployment. Text Understanding on par with pure LLMs: Seamless text–vision…

Read QuantTrio's full model card

Base Model: Qwen/Qwen3-VL-30B-A3B-Instruct

【Dependencies / Installation】

As of 2025-10-08, create a fresh Python environment and run:

uv venv
source .venv/bin/activate

# Install vLLM >=0.11.0
uv pip install -U vllm

# Install Qwen-VL utility library (recommended for offline inference)
uv pip install qwen-vl-utils==0.0.14

For more details, refer to vLLM Official Qwen3-VL Guide

【vLLM Startup Command】

CONTEXT_LENGTH=32768

vllm serve \
    tclf90/Qwen3-VL-30B-A3B-Instruct-AWQ \
    --served-model-name My_Model \
    --swap-space 4 \
    --max-num-seqs 8 \
    --max-model-len $CONTEXT_LENGTH \
    --gpu-memory-utilization 0.9 \
    --tensor-parallel-size 2 \
    --trust-remote-code \
    --disable-log-requests \
    --host 0.0.0.0 \
    --port 8000

【Logs】

2025-10-04
1. Initial commit

【Model Files】

File Size Last Updated
17GB 2025-10-04

【Model Download】

from modelscope import snapshot_download
snapshot_download('tclf90/Qwen3-VL-30B-A3B-Instruct-AWQ', cache_dir="your_local_path")

【Overview】

Qwen3-VL-30B-A3B-Instruct

Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date.

This generation delivers comprehensive upgrades across the board: superior text understanding & generation, deeper visual perception & reasoning, extended context length, enhanced spatial and video dynamics comprehension, and stronger agent interaction capabilities.

Available in Dense and MoE architectures that scale from edge to cloud, with Instruct and reasoning‑enhanced Thinking editions for flexible, on‑demand deployment.

Key Enhancements:

  • Visual Agent: Operates PC/mobile GUIs—recognizes elements, understands functions, invokes tools, completes tasks.

  • Visual Coding Boost: Generates Draw.io/HTML/CSS/JS from images/videos.

  • Advanced Spatial Perception: Judges object positions, viewpoints, and occlusions; provides stronger 2D grounding and enables 3D grounding for spatial reasoning and embodied AI.

  • Long Context & Video Understanding: Native 256K context, expandable to 1M; handles books and hours-long video with full recall and second-level indexing.

  • Enhanced Multimodal Reasoning: Excels in STEM/Math—causal analysis and logical, evidence-based answers.

  • Upgraded Visual Recognition: Broader, higher-quality pretraining is able to “recognize everything”—celebrities, anime, products, landmarks, flora/fauna, etc.

  • Expanded OCR: Supports 32 languages (up from 19); robust in low light, blur, and tilt; better with rare/ancient characters and jargon; improved long-document structure parsing.

  • Text Understanding on par with pure LLMs: Seamless text–vision fusion for lossless, unified comprehension.

Model Architecture Updates:

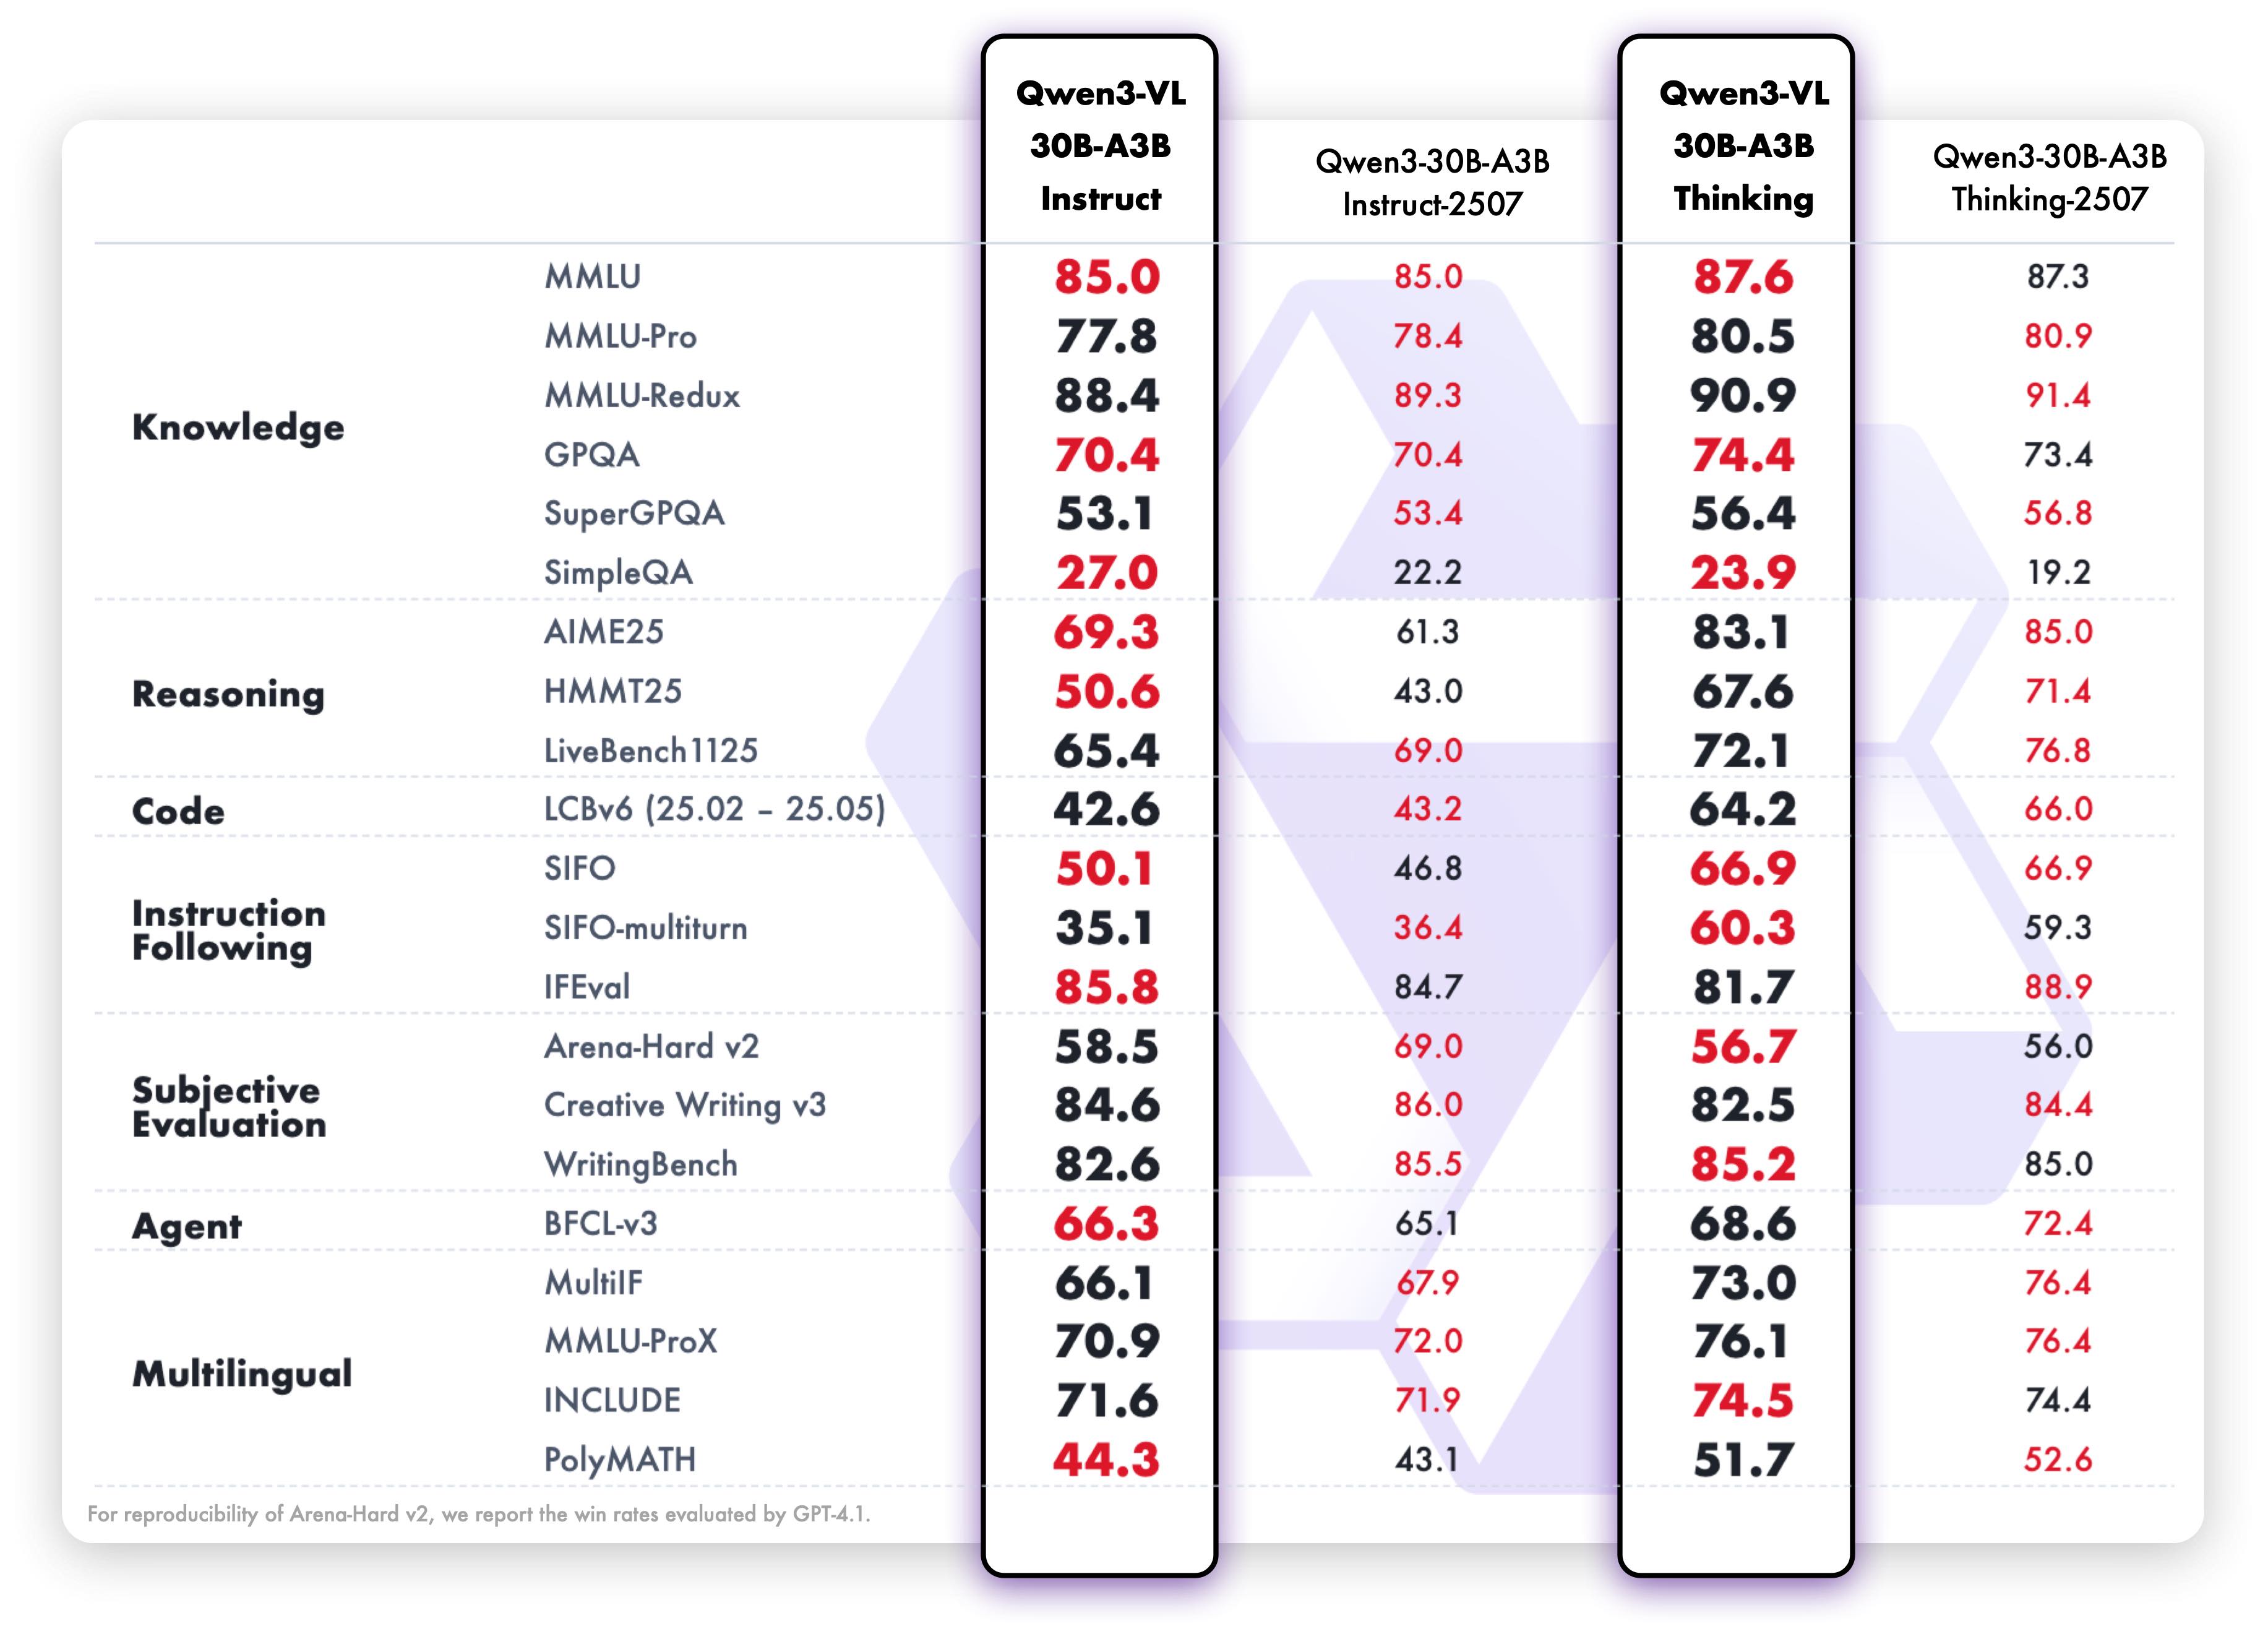
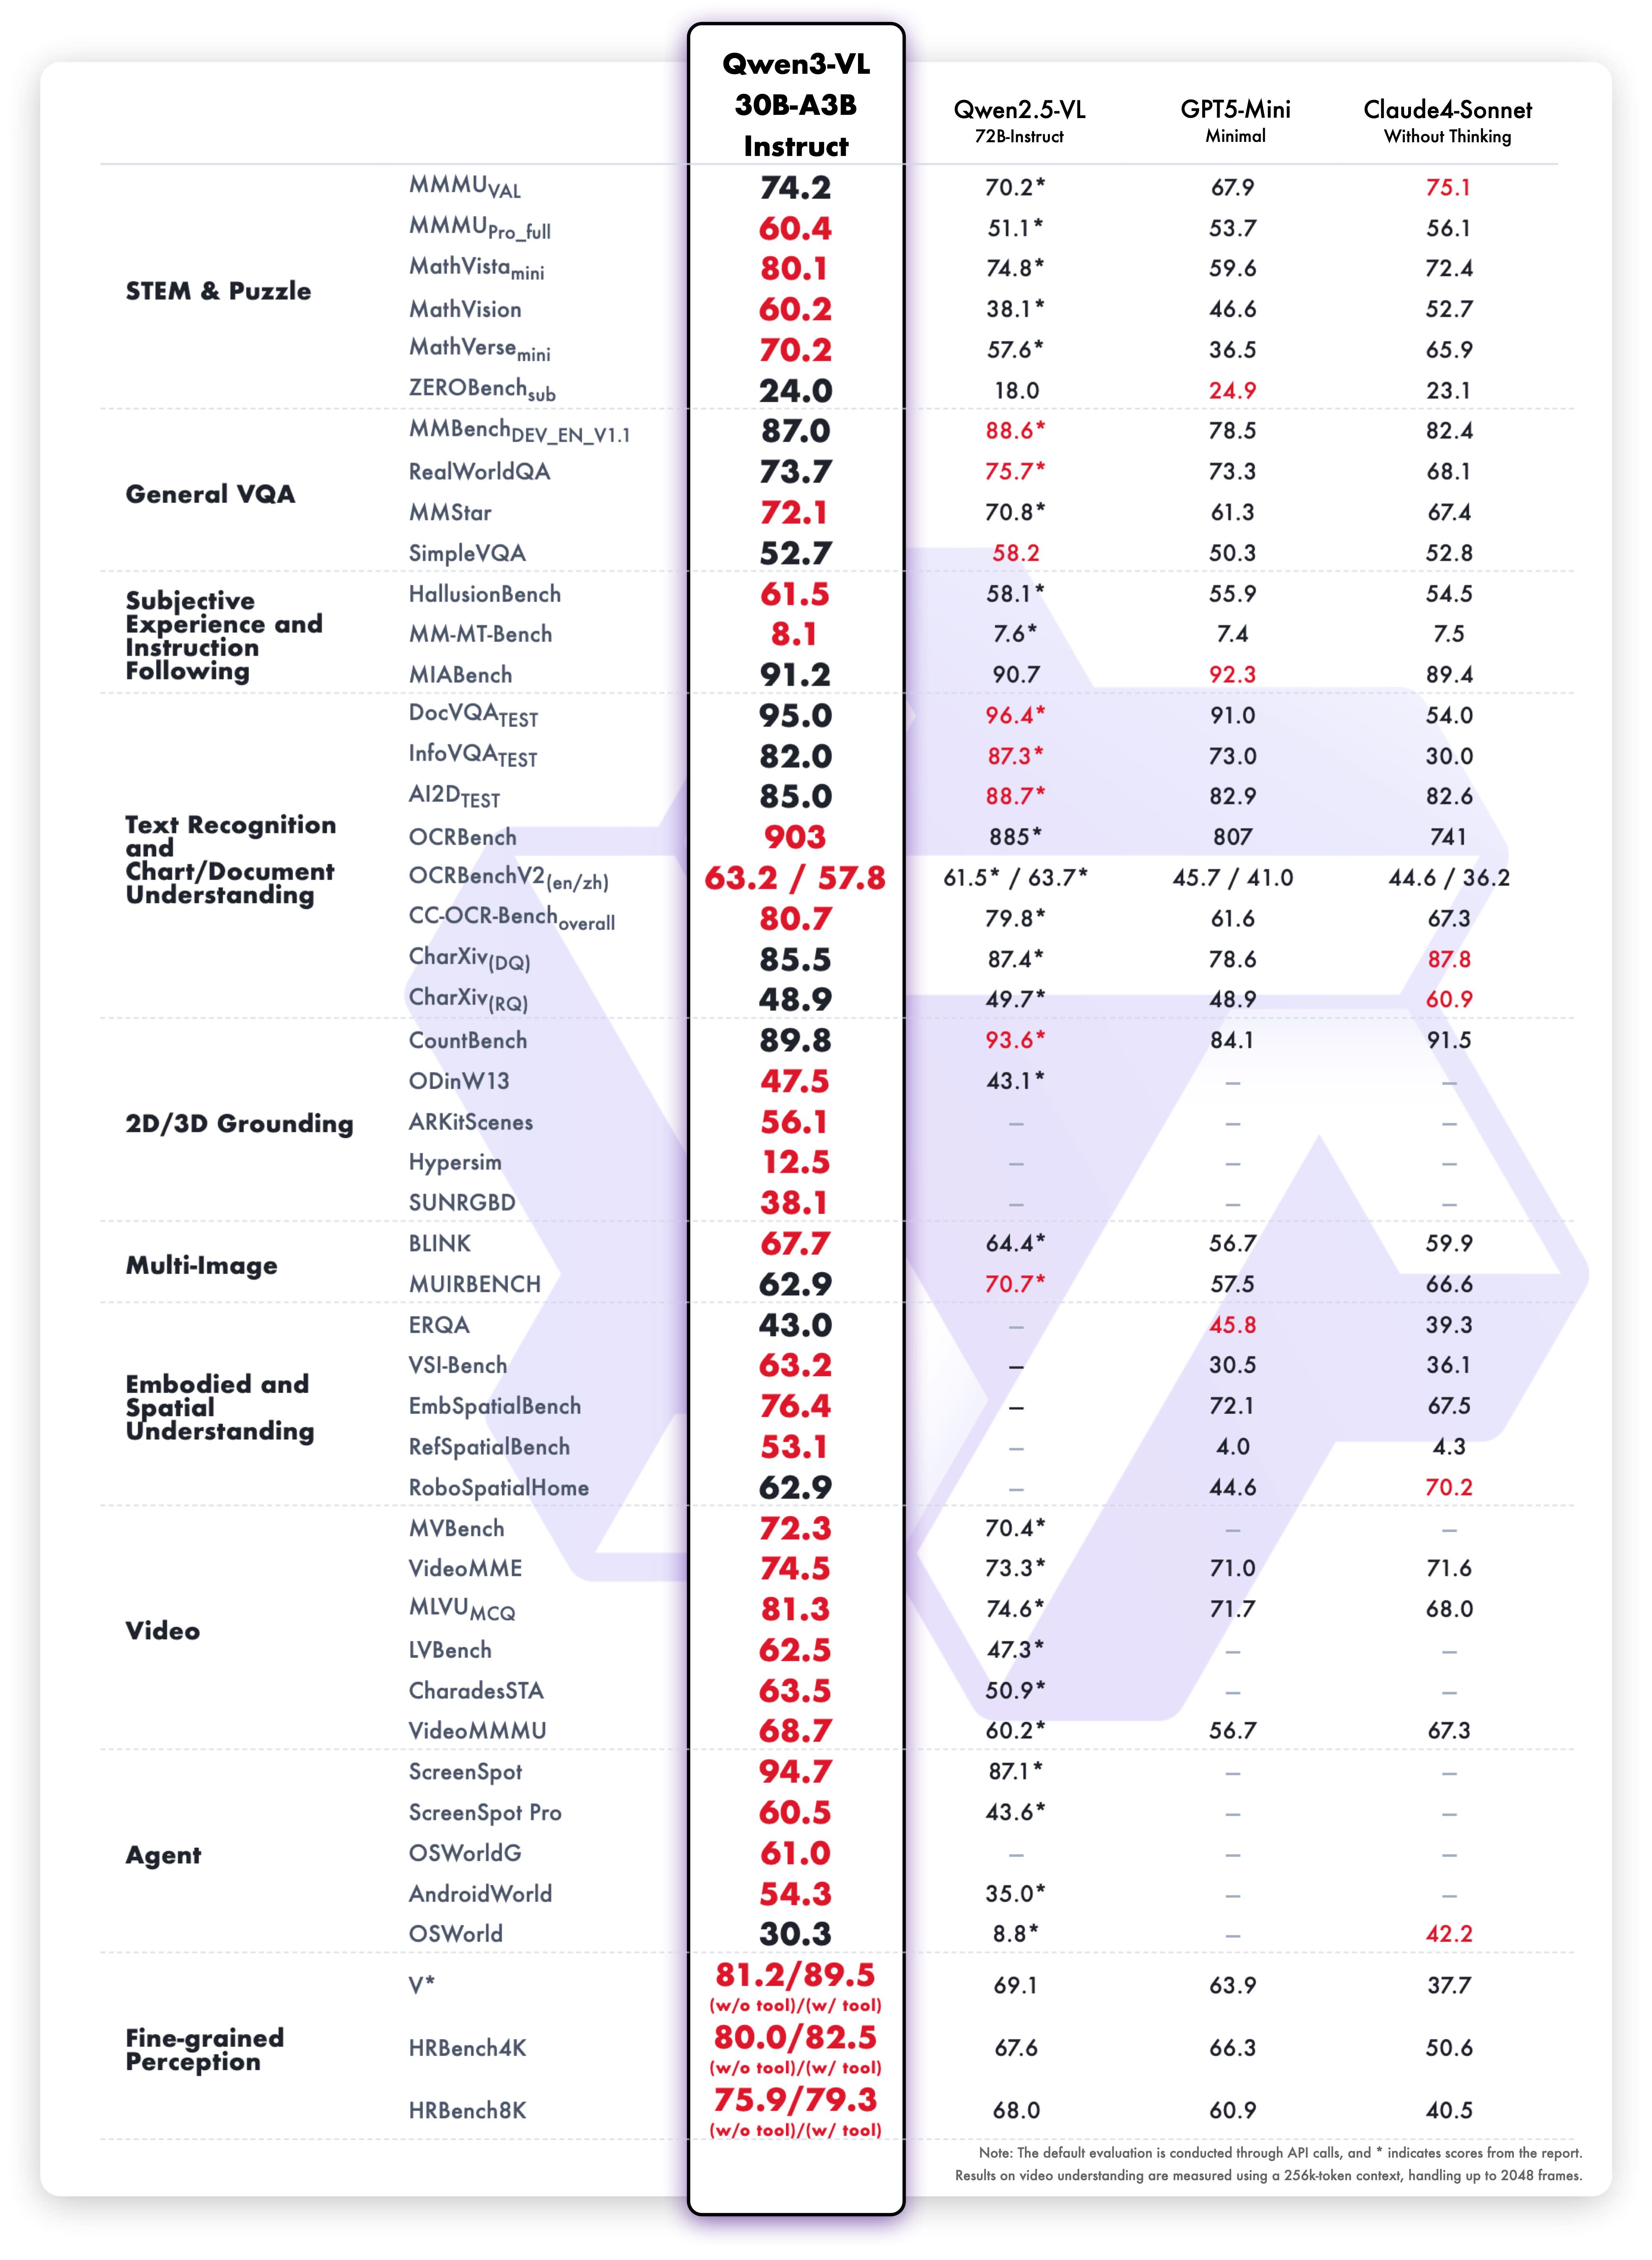
1. **Interleaved-MRoPE**: Full‑frequency allocation over time, width, and height via robust positional embeddings, enhancing long‑horizon video reasoning. 2. **DeepStack**: Fuses multi‑level ViT features to capture fine‑grained details and sharpen image–text alignment. 3. **Text–Timestamp Alignment:** Moves beyond T‑RoPE to precise, timestamp‑grounded event localization for stronger video temporal modeling. This is the weight repository for Qwen3-VL-30B-A3B-Instruct. --- ## Model Performance **Multimodal performance** ![](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3-VL/table_nothinking_vl-30a3.jpg) **Pure text performance** ![](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3-VL/table_nothinking_text-30a3.jpg) ## Quickstart Below, we provide simple examples to show how to use Qwen3-VL with ModelScope and Transformers. The code of Qwen3-VL has been in the latest Hugging Face transformers and we advise you to build from source with command:
pip install git+https://github.com/huggingface/transformers
# pip install transformers==4.57.0 # currently, V4.57.0 is not released
### Using Transformers to Chat Here we show a code snippet to show how to use the chat model with `transformers`:
from transformers import Qwen3VLMoeForConditionalGeneration, AutoProcessor

# default: Load the model on the available device(s)
model = Qwen3VLMoeForConditionalGeneration.from_pretrained(
    "Qwen/Qwen3-VL-30B-A3B-Instruct", dtype="auto", device_map="auto"
)

# We recommend enabling flash_attention_2 for better acceleration and memory saving, especially in multi-image and video scenarios.
# model = Qwen3VLMoeForConditionalGeneration.from_pretrained(
#     "Qwen/Qwen3-VL-30B-A3B-Instruct",
#     dtype=torch.bfloat16,
#     attn_implementation="flash_attention_2",
#     device_map="auto",
# )

processor = AutoProcessor.from_pretrained("Qwen/Qwen3-VL-30B-A3B-Instruct")

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image",
                "image": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg",
            },
            {"type": "text", "text": "Describe this image."},
        ],
    }
]

# Preparation for inference
inputs = processor.apply_chat_template(
    messages,
    tokenize=True,
    add_generation_prompt=True,
    return_dict=True,
    return_tensors="pt"
)

# Inference: Generation of the output
generated_ids = model.generate(**inputs, max_new_tokens=128)
generated_ids_trimmed = [
    out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text)
## Citation If you find our work helpful, feel free to give us a cite.
@misc{qwen3technicalreport,
      title={Qwen3 Technical Report}, 
      author={Qwen Team},
      year={2025},
      eprint={2505.09388},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2505.09388}, 
}

@article{Qwen2.5-VL,
  title={Qwen2.5-VL Technical Report},
  author={Bai, Shuai and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Song, Sibo and Dang, Kai and Wang, Peng and Wang, Shijie and Tang, Jun and Zhong, Humen and Zhu, Yuanzhi and Yang, Mingkun and Li, Zhaohai and Wan, Jianqiang and Wang, Pengfei and Ding, Wei and Fu, Zheren and Xu, Yiheng and Ye, Jiabo and Zhang, Xi and Xie, Tianbao and Cheng, Zesen and Zhang, Hang and Yang, Zhibo and Xu, Haiyang and Lin, Junyang},
  journal={arXiv preprint arXiv:2502.13923},
  year={2025}
}

@article{Qwen2VL,
  title={Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution},
  author={Wang, Peng and Bai, Shuai and Tan, Sinan and Wang, Shijie and Fan, Zhihao and Bai, Jinze and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Fan, Yang and Dang, Kai and Du, Mengfei and Ren, Xuancheng and Men, Rui and Liu, Dayiheng and Zhou, Chang and Zhou, Jingren and Lin, Junyang},
  journal={arXiv preprint arXiv:2409.12191},
  year={2024}
}

@article{Qwen-VL,
  title={Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond},
  author={Bai, Jinze and Bai, Shuai and Yang, Shusheng and Wang, Shijie and Tan, Sinan and Wang, Peng and Lin, Junyang and Zhou, Chang and Zhou, Jingren},
  journal={arXiv preprint arXiv:2308.12966},
  year={2023}
}

Configuration

Architecture
Qwen3VLMoeForConditionalGeneration
Context length (tokens)
262,144
Layers
48
Hidden size
2,048
Feed-forward size
6,144
Attention heads
32
Key/value heads
4
Head dimension
128
Vocabulary size
151,936
Experts
128
Experts active per token
8
RoPE base
5,000,000
Stored precision
float16
Model type
qwen3_vl_moe
Quantization
awq

Identity and Version

Repository
QuantTrio/Qwen3-VL-30B-A3B-Instruct-AWQ
Publisher
QuantTrio
Task
Text generation
Modality
Text
Library
transformers
Parameters
31.1B parameters
Languages
awq
Revision
a5ea10732e2c9330957864ece3ec66d806a4b00d
First published
2025-10-04
Last updated
2025-10-08

Files and Weights

19 files, 17.9 GB in total. The weights are 6 files totalling 17.9 GB in safetensors.

Weights6 files · 17.9 GB
Configuration7 files · 6.0 MB
Tokenizer4 files · 11.5 MB
Documentation1 file · 8.1 KB
Repository1 file · 1.5 KB
Every file
FileTypeSizeSHA-256
model-00001-of-00006.safetensorsWeights3.0 GB f1b85a58d250
model-00002-of-00006.safetensorsWeights3.0 GB 3d1f9b536862
model-00003-of-00006.safetensorsWeights3.0 GB 14c74063c6f6
model-00004-of-00006.safetensorsWeights3.0 GB 797ecde74955
model-00005-of-00006.safetensorsWeights3.0 GB ad04cbd1635a
model-00006-of-00006.safetensorsWeights2.9 GB e4299ea234b3
chat_template.jsonConfiguration5.5 KB
config.jsonConfiguration2.0 KB
configuration.jsonConfiguration51 B
generation_config.jsonConfiguration269 B
model.safetensors.index.jsonConfiguration5.9 MB
preprocessor_config.jsonConfiguration390 B
video_preprocessor_config.jsonConfiguration385 B
README.mdDocumentation8.1 KB
.gitattributesRepository1.5 KB
merges.txtTokenizer1.7 MB
tokenizer.jsonTokenizer7.0 MB
tokenizer_config.jsonTokenizer10.9 KB
vocab.jsonTokenizer2.8 MB

License and Download

License
apache-2.0
Access
Open weights, no gate
Download size
17.9 GB
Download from QuantTrio

Released by QuantTrio through its official repository on Hugging Face. Read the license.

Built From

Memory Requirements

PrecisionWeights in memory
As published17.9 GB
16-bit62.1 GB
8-bit31.1 GB
4-bit15.5 GB

Weights only, from the published parameter count; the key-value cache and runtime add to this.

Questions About Qwen3-VL-30B-A3B-Instruct-AWQ

How much GPU memory does Qwen3-VL-30B-A3B-Instruct-AWQ need?

About 74.6 GB at 16-bit and 18.6 GB at 4-bit: the weights (31.1B parameters) plus a working margin. A long context needs more.

What is the cheapest GPU to run Qwen3-VL-30B-A3B-Instruct-AWQ on?

At 16-bit, 1x MI300X from $1.85 an hour; at 4-bit, 1x MI300X from $1.85 an hour, at the lowest on-demand prices the SAVRN Index lists.

Can I use Qwen3-VL-30B-A3B-Instruct-AWQ commercially?

Yes. Qwen3-VL-30B-A3B-Instruct-AWQ is released under Apache License 2.0. The Apache License 2.0 is a permissive open-source license. It permits commercial use, modification and redistribution. It requires keeping the license and copyright notices and any NOTICE file, stating significant changes, and it includes an express patent grant from contributors.

What is Qwen3-VL-30B-A3B-Instruct-AWQ's context length?

262,144 tokens, from the maximum position embeddings in its published configuration.

Similar Models

Model · Text generation

GLM-4.7-Flash

Z.ai

Join our Discord community. Check out the GLM-4.7 technical blog, technical report(GLM-4.5). Use GLM-4.7-Flash API services on Z.ai API Platform. One click to GLM-4.7. GLM-4.7-Flash is a 30B-A3B MoE model. As the strongest model in the 30B class, GLM-4.7-Flash offers a new option for lightweight deployment that balances performance and efficiency. Default Settings (Most Tasks) For multi-turn agentic tasks (τ²-Bench and Terminal Bench 2), please turn on Preserved Thinking mode. Terminal Bench, SWE Bench Verified τ^2-Bench For τ^2-Bench evaluation, we added an additional prompt to the Retail and Telecom user interaction to avoid failure modes caused by users ending the interaction…

Open weights mit 31.2B parameters 202,752 tokens transformers

Model · Text generation

OTel-2.0-LLM-31B-IT

Farbod Tavakkoli

OTel-2.0-LLM-31B-IT is a telecom-specialized instruction model post-trained from Gemma 4 31B-IT on approximately 440 billion telecom training tokens. It is the first release in the OTel 2.0 family and is designed to support telco-grade AI workflows across network operations, standards interpretation, product development, network configuration assistance, RAG, and telecom-specific question answering. OTel 2.0 extends the original OTel effort from a RAG-oriented telecom fine-tuning release into a larger domain-adapted training program. The model was trained from a much larger standards and telecom corpus, with new data preparation coverage for direct telecom QnA, abstention, RAG…

Open weights apache-2.0 31.3B parameters 262,144 tokens transformers

Model · Text generation

NVIDIA-Nemotron-3-Nano-30B-A3B-BF16

NVIDIA

September 2025 \- December 2025 The post-training data has a cutoff date of November 28, 2025\. The pre-training data has a cutoff date of June 25, 2025\. Nemotron-3-Nano-30B-A3B-BF16 is a large language model (LLM) trained from scratch by NVIDIA, and designed as a unified model for both reasoning and non-reasoning tasks. It responds to user queries and tasks by first generating a reasoning trace and then concluding with a final response. The model's reasoning capabilities can be configured through a flag in the chat template. If the user prefers the model to provide its final answer without intermediate reasoning traces, it can be configured to do so, albeit with a slight decrease in…

Open weights other 31.6B parameters 262,144 tokens transformers

Fastino-Nemotron-3.5-Lightning-Finance is a 30B-parameter, 3B-active mixture-of-experts model specialized for financial reasoning, extraction, and research fine-tuned on LoRA with the Fastino Fine-Tuning Agent. The model targets financial document reasoning, numerical question answering over filings and tables, numeric span extraction, financial entity recognition, conversational analysis, and source-grounded financial research. The evaluation suite includes FinQA, TAT-QA, SEC-Num, FinEntity, BizFinBench, BigFinanceBench, ConvFinQA, and FiQA. The published weights are BF16 and require about 66 GB before runtime overhead. An 80 GB or larger GPU, or tensor parallelism across multiple GPUs, is…

Open weights apache-2.0 31.6B parameters 262,144 tokens transformers

Model · Text generation

Qwen3-Coder-30B-A3B-Instruct-FP8

Qwen

Qwen3-Coder is available in multiple sizes. Today, we're excited to introduce Qwen3-Coder-30B-A3B-Instruct-FP8. This streamlined model maintains impressive performance and efficiency, featuring the following key enhancements: - Significant Performance among open models on Agentic Coding, Agentic Browser-Use, and other foundational coding tasks. - Long-context Capabilities with native support for 256K tokens, extendable up to 1M tokens using Yarn, optimized for repository-scale understanding. - Agentic Coding supporting for most platform such as Qwen Code, CLINE, featuring a specially designed function call format. Qwen3-Coder-30B-A3B-Instruct-FP8 has the following features: NOTE: This model…

Open weights apache-2.0 30.5B parameters 262,144 tokens transformers