SAVRN
Search Contact SAVRN

Open-weight model · Image and text to text

Qwen3-VL-8B-Instruct-FP8

by Qwen Qwen/Qwen3-VL-8B-Instruct-FP8

Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date.

Parameters8.8B
Context262,144
Weights10.6 GB
Licenseapache-2.0
AccessOpen weights
Monthly Downloads2.5M

Runs On

What it takes to serve Qwen3-VL-8B-Instruct-FP8 (8.8B parameters): the memory its weights need at each precision, and the cheapest way to rent enough data-center GPUs to hold them.

PrecisionWeightsMemory neededCheapest setupPer hourAlso fits
16-bit 17.5 GB 21.0 GB 1x MI300X (192 GB)
Vultr
$1.85 1x H100 $1.99 · 1x MI325X $2.00
8-bit 8.8 GB 10.5 GB 1x MI300X (192 GB)
Vultr
$1.85 1x H100 $1.99 · 1x MI325X $2.00
4-bit 4.4 GB 5.3 GB 1x MI300X (192 GB)
Vultr
$1.85 1x H100 $1.99 · 1x MI325X $2.00

Memory is the weights at that precision plus 20% for the runtime and a short context; a long context needs more. Prices are the lowest on-demand hourly rates in the SAVRN Index, read Sep 18, 2026.

Model Card

By Qwen, published under apache-2.0, revision 9cdc6310a8cb.

Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date. This generation delivers comprehensive upgrades across the board: superior text understanding & generation, deeper visual perception & reasoning, extended context length, enhanced spatial and video dynamics comprehension, and stronger agent interaction capabilities. Available in Dense and MoE architectures that scale from edge to cloud, with Instruct and reasoning‑enhanced Thinking editions for flexible, on‑demand deployment. Text Understanding on par with pure LLMs: Seamless text–vision fusion for lossless, unified comprehension. 1. Interleaved-MRoPE: Full‑frequency allocation over time, width, and height…

Read Qwen's full model card

This repository contains an FP8 quantized version of the Qwen3-VL-8B-Instruct model. The quantization method is fine-grained fp8 quantization with block size of 128, and its performance metrics are nearly identical to those of the original BF16 model. Enjoy!

Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date.

This generation delivers comprehensive upgrades across the board: superior text understanding & generation, deeper visual perception & reasoning, extended context length, enhanced spatial and video dynamics comprehension, and stronger agent interaction capabilities.

Available in Dense and MoE architectures that scale from edge to cloud, with Instruct and reasoning‑enhanced Thinking editions for flexible, on‑demand deployment.

Key Enhancements:

  • Visual Agent: Operates PC/mobile GUIs—recognizes elements, understands functions, invokes tools, completes tasks.

  • Visual Coding Boost: Generates Draw.io/HTML/CSS/JS from images/videos.

  • Advanced Spatial Perception: Judges object positions, viewpoints, and occlusions; provides stronger 2D grounding and enables 3D grounding for spatial reasoning and embodied AI.

  • Long Context & Video Understanding: Native 256K context, expandable to 1M; handles books and hours-long video with full recall and second-level indexing.

  • Enhanced Multimodal Reasoning: Excels in STEM/Math—causal analysis and logical, evidence-based answers.

  • Upgraded Visual Recognition: Broader, higher-quality pretraining is able to “recognize everything”—celebrities, anime, products, landmarks, flora/fauna, etc.

  • Expanded OCR: Supports 32 languages (up from 19); robust in low light, blur, and tilt; better with rare/ancient characters and jargon; improved long-document structure parsing.

  • Text Understanding on par with pure LLMs: Seamless text–vision fusion for lossless, unified comprehension.

Model Architecture Updates:

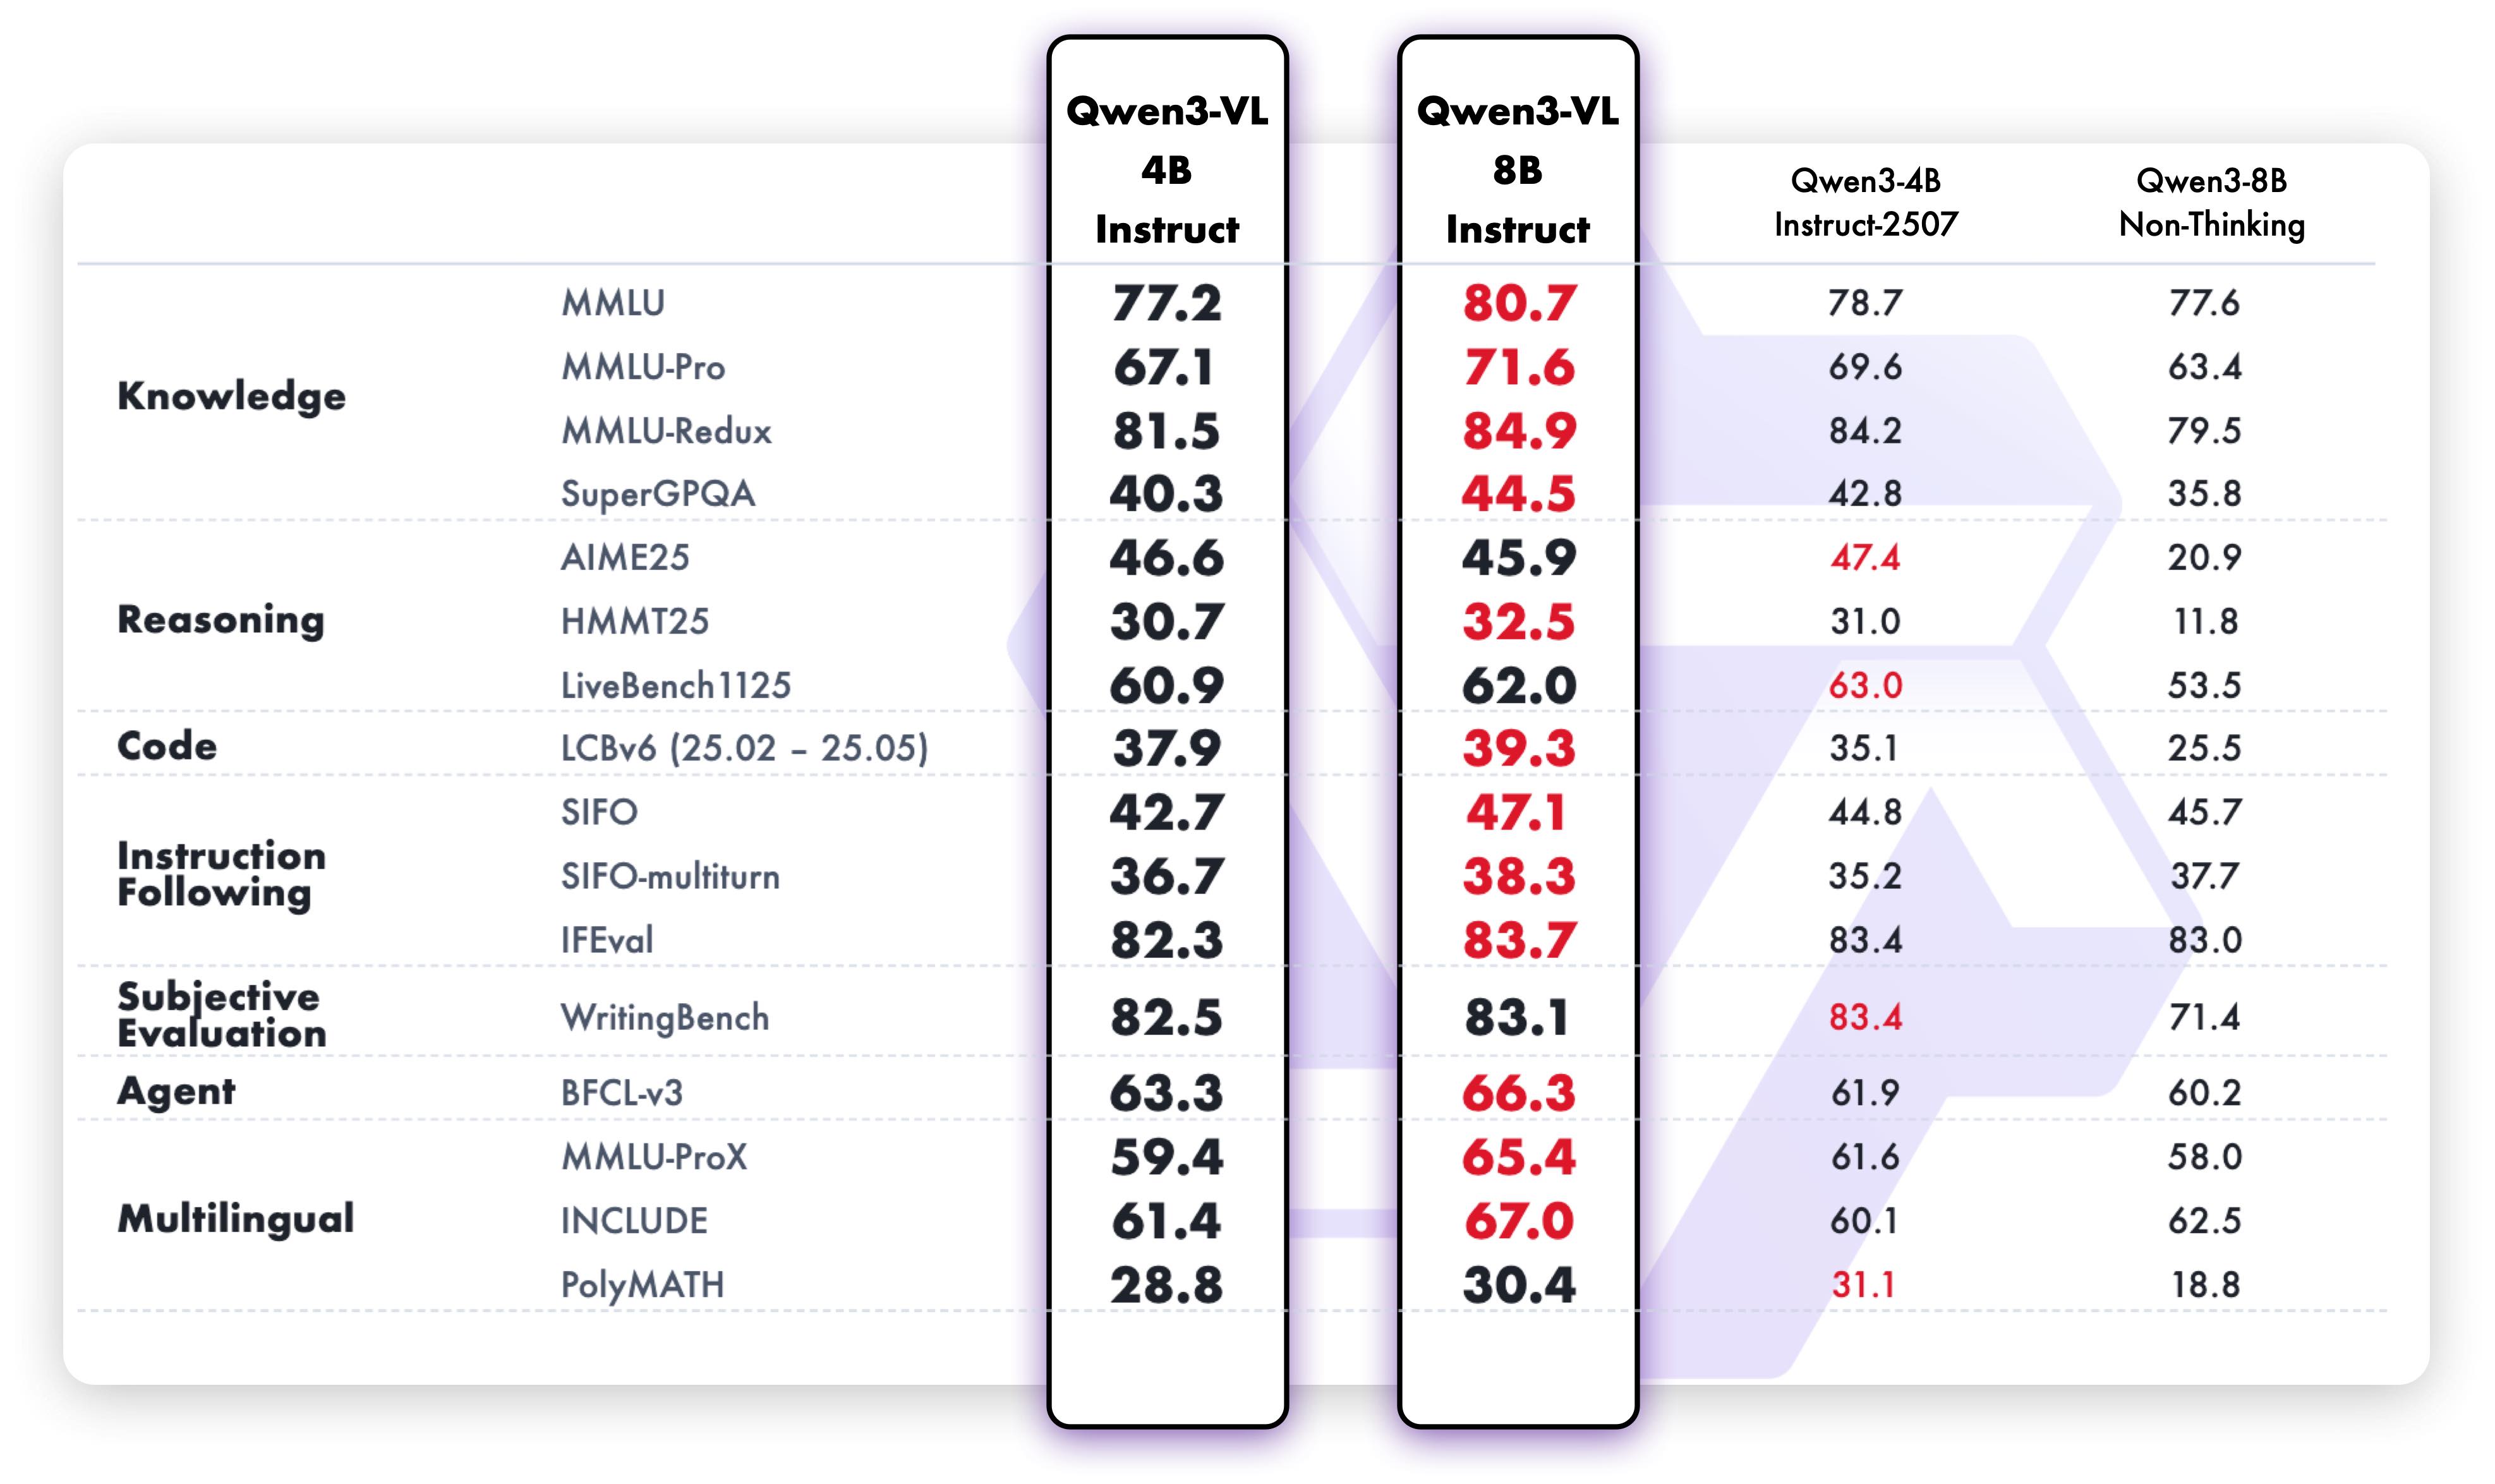
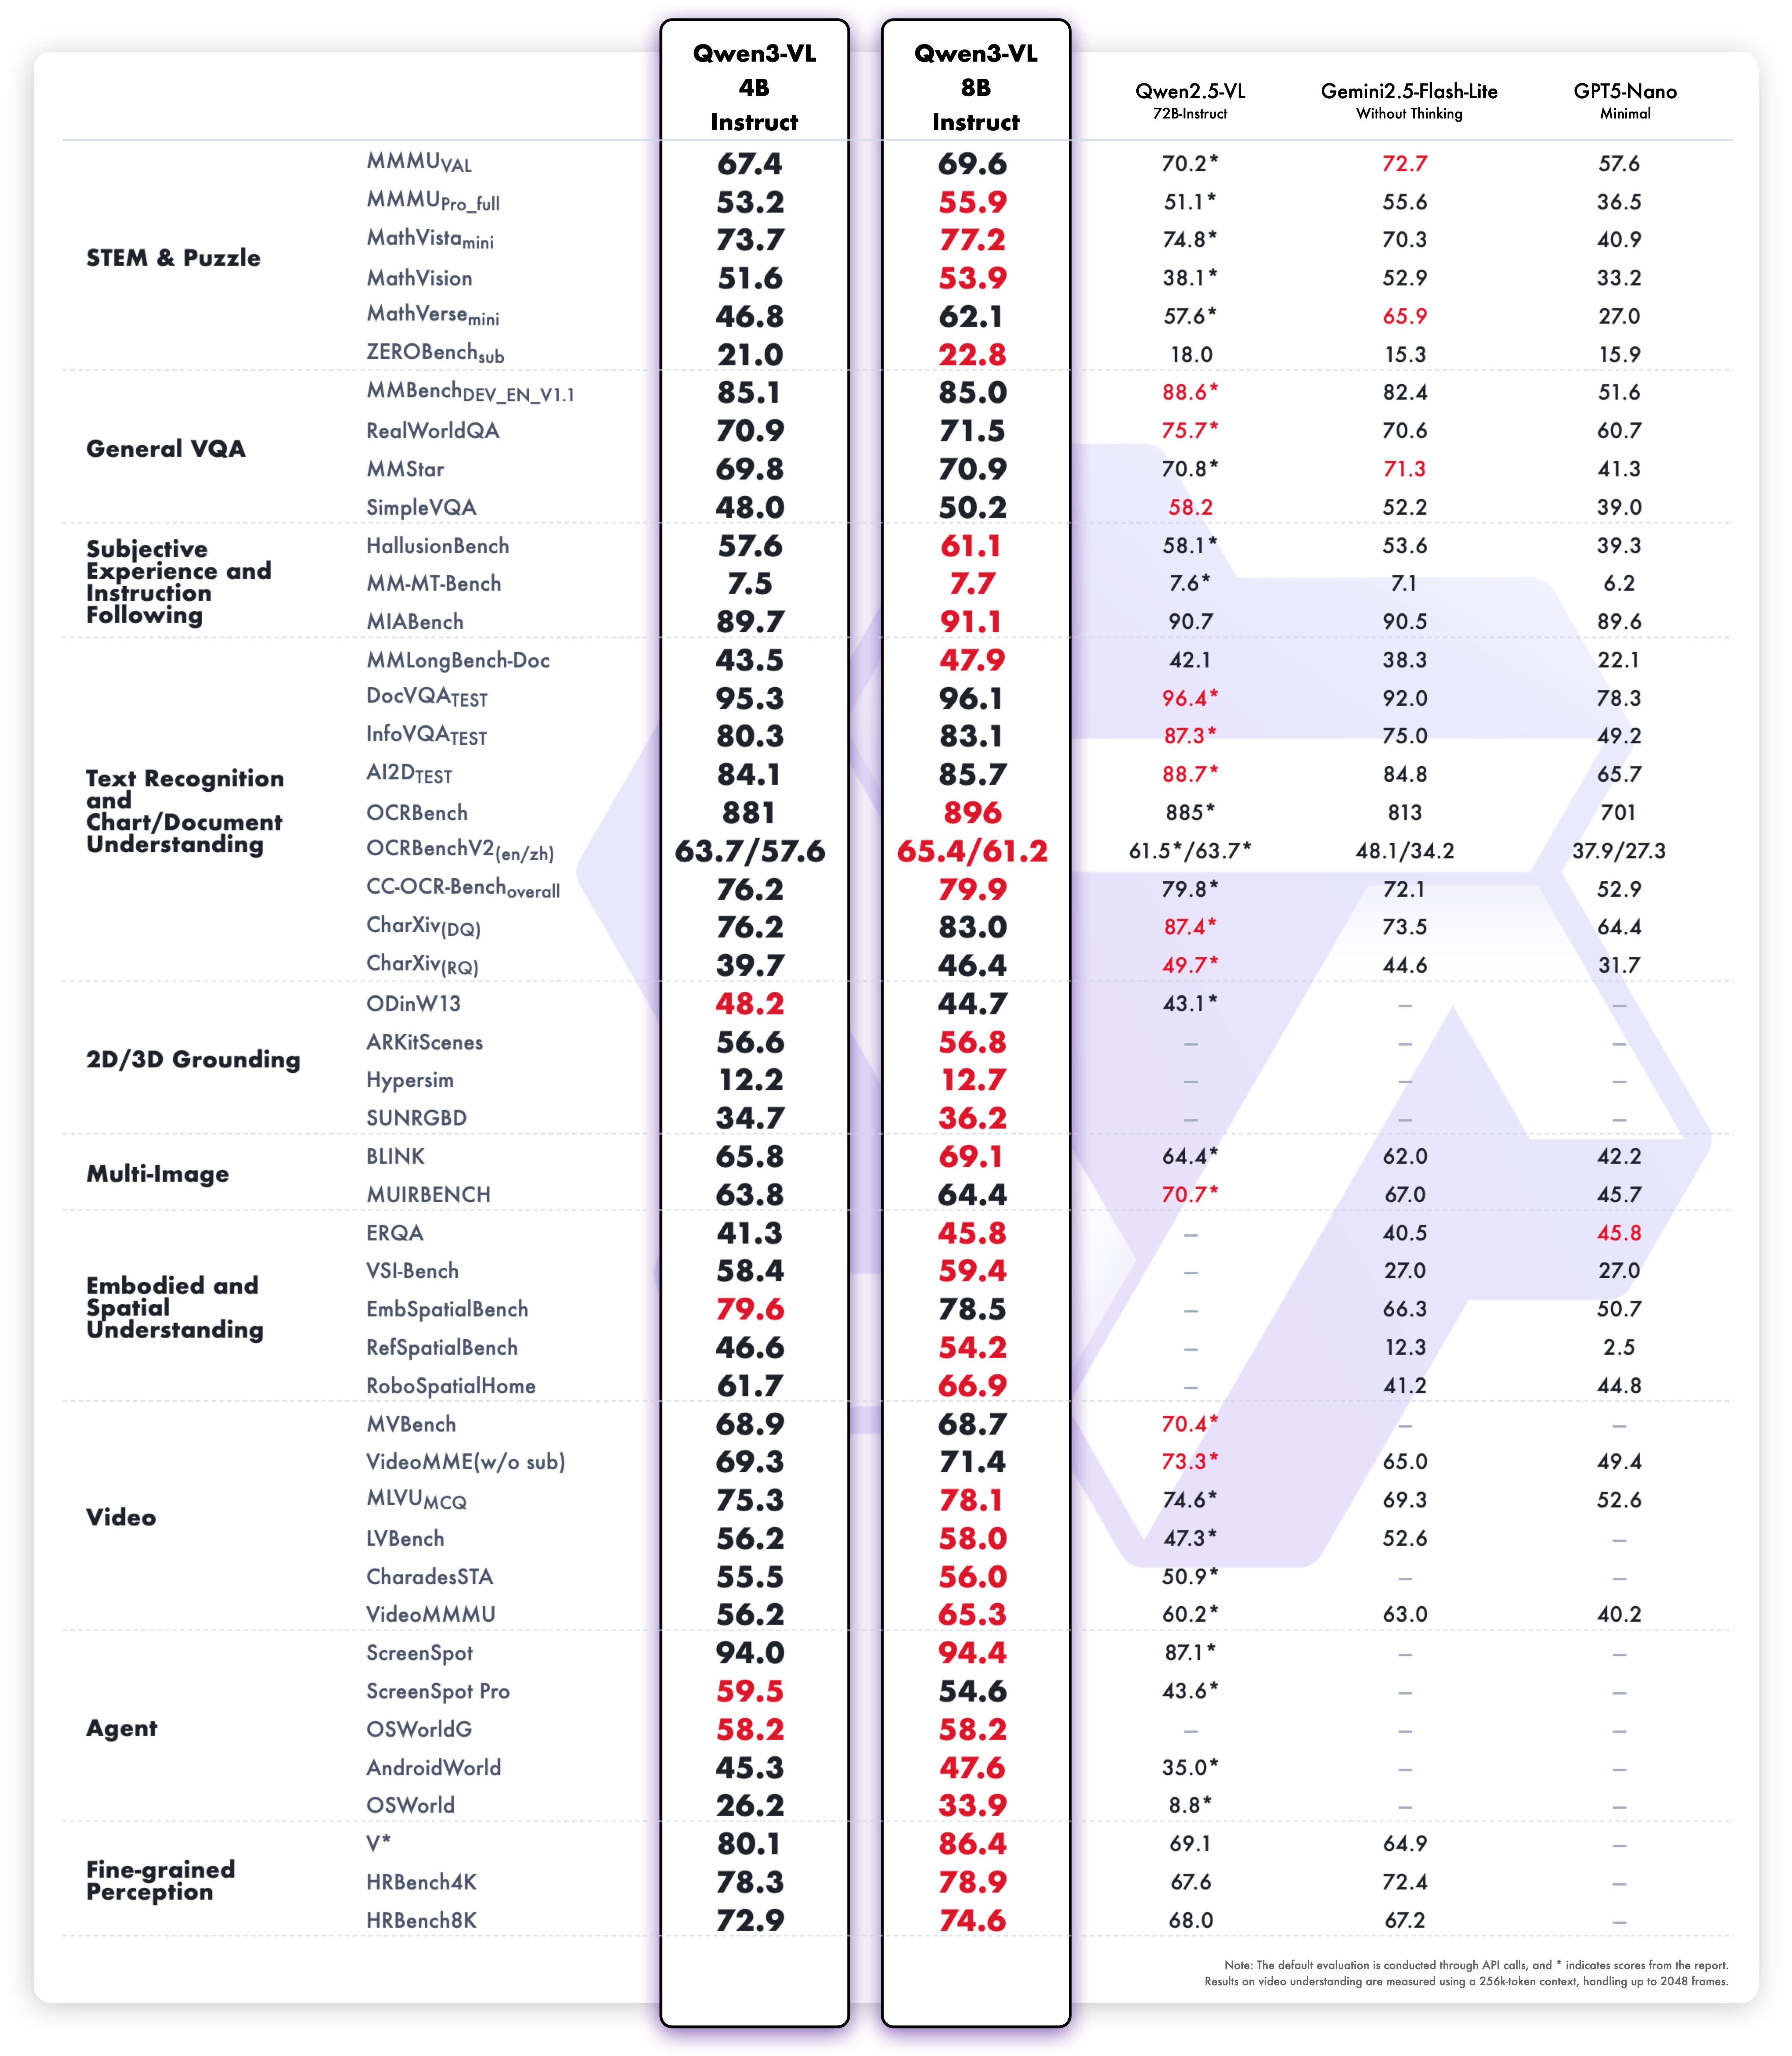
1. **Interleaved-MRoPE**: Full‑frequency allocation over time, width, and height via robust positional embeddings, enhancing long‑horizon video reasoning. 2. **DeepStack**: Fuses multi‑level ViT features to capture fine‑grained details and sharpen image–text alignment. 3. **Text–Timestamp Alignment:** Moves beyond T‑RoPE to precise, timestamp‑grounded event localization for stronger video temporal modeling. This is the weight repository for Qwen3-VL-8B-Instruct-FP8. --- ## Model Performance **Multimodal performance** ![](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3-VL/qwen3vl_4b_8b_vl_instruct.jpg) **Pure text performance** ![](https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3-VL/qwen3vl_4b_8b_text_instruct.jpg) ## Quickstart Currently, Transformers does not support loading these weights directly. Stay tuned! We recommend deploying the model using vLLM or SGLang, with example launch commands provided below. For details on the runtime environment and deployment, please refer to this [link](https://github.com/QwenLM/Qwen3-VL?tab=readme-ov-file#deployment). ### vLLM Inference Here we provide a code snippet demonstrating how to use vLLM to run inference with Qwen3-VL locally. For more details on efficient deployment with vLLM, please refer to the [community deployment guide](https://docs.vllm.ai/projects/recipes/en/latest/Qwen/Qwen3-VL.html).
# -*- coding: utf-8 -*-
import torch
from qwen_vl_utils import process_vision_info
from transformers import AutoProcessor
from vllm import LLM, SamplingParams

import os
os.environ['VLLM_WORKER_MULTIPROC_METHOD'] = 'spawn'

def prepare_inputs_for_vllm(messages, processor):
    text = processor.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
    # qwen_vl_utils 0.0.14+ reqired
    image_inputs, video_inputs, video_kwargs = process_vision_info(
        messages,
        image_patch_size=processor.image_processor.patch_size,
        return_video_kwargs=True,
        return_video_metadata=True
    )
    print(f"video_kwargs: {video_kwargs}")

    mm_data = {}
    if image_inputs is not None:
        mm_data['image'] = image_inputs
    if video_inputs is not None:
        mm_data['video'] = video_inputs

    return {
        'prompt': text,
        'multi_modal_data': mm_data,
        'mm_processor_kwargs': video_kwargs
    }


if __name__ == '__main__':
    # messages = [
    #     {
    #         "role": "user",
    #         "content": [
    #             {
    #                 "type": "video",
    #                 "video": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-VL/space_woaudio.mp4",
    #             },
    #             {"type": "text", "text": "这段视频有多长"},
    #         ],
    #     }
    # ]

    messages = [
        {
            "role": "user",
            "content": [
              {
                  "type": "image",
                  "image": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3-VL/receipt.png",
              },
              {"type": "text", "text": "Read all the text in the image."},
            ],
        }
    ]

    # TODO: change to your own checkpoint path
    checkpoint_path = "Qwen/Qwen3-VL-8B-Instruct-FP8"
    processor = AutoProcessor.from_pretrained(checkpoint_path)
    inputs = [prepare_inputs_for_vllm(message, processor) for message in [messages]]

    llm = LLM(
        model=checkpoint_path,
        trust_remote_code=True,
        gpu_memory_utilization=0.70,
        enforce_eager=False,
        tensor_parallel_size=torch.cuda.device_count(),
        seed=0
    )

    sampling_params = SamplingParams(
        temperature=0,
        max_tokens=1024,
        top_k=-1,
        stop_token_ids=[],
    )

    for i, input_ in enumerate(inputs):
        print()
        print('=' * 40)
        print(f"Inputs[{i}]: {input_['prompt']=!r}")
    print('\n' + '>' * 40)

    outputs = llm.generate(inputs, sampling_params=sampling_params)
    for i, output in enumerate(outputs):
        generated_text = output.outputs[0].text
        print()
        print('=' * 40)
        print(f"Generated text: {generated_text!r}")
### SGLang Inference Here we provide a code snippet demonstrating how to use SGLang to run inference with Qwen3-VL locally.
import time
from PIL import Image
from sglang import Engine
from qwen_vl_utils import process_vision_info
from transformers import AutoProcessor, AutoConfig

if __name__ == "__main__":
    # TODO: change to your own checkpoint path
    checkpoint_path = "Qwen/Qwen3-VL-8B-Instruct-FP8"
    processor = AutoProcessor.from_pretrained(checkpoint_path)

    messages = [
        {
            "role": "user",
            "content": [
              {
                  "type": "image",
                  "image": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3-VL/receipt.png",
              },
              {"type": "text", "text": "Read all the text in the image."},
            ],
        }
    ]

    text = processor.apply_chat_template(
        messages,
        tokenize=False,
        add_generation_prompt=True
    )

    image_inputs, _ = process_vision_info(messages, image_patch_size=processor.image_processor.patch_size)

    llm = Engine(
        model_path=checkpoint_path,
        enable_multimodal=True,
        mem_fraction_static=0.8,
        tp_size=torch.cuda.device_count(),
        attention_backend="fa3"
    )

    start = time.time()
    sampling_params = {"max_new_tokens": 1024}
    response = llm.generate(prompt=text, image_data=image_inputs, sampling_params=sampling_params)
    print(f"Response costs: {time.time() - start:.2f}s")
    print(f"Generated text: {response['text']}")
### Generation Hyperparameters #### VL
export greedy='false'
export top_p=0.8
export top_k=20
export temperature=0.7
export repetition_penalty=1.0
export presence_penalty=1.5
export out_seq_length=16384
#### Text
export greedy='false'
export top_p=1.0
export top_k=40
export repetition_penalty=1.0
export presence_penalty=2.0
export temperature=1.0
export out_seq_length=32768
## Citation If you find our work helpful, feel free to give us a cite.
@misc{qwen3technicalreport,
      title={Qwen3 Technical Report}, 
      author={Qwen Team},
      year={2025},
      eprint={2505.09388},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2505.09388}, 
}

@article{Qwen2.5-VL,
  title={Qwen2.5-VL Technical Report},
  author={Bai, Shuai and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Song, Sibo and Dang, Kai and Wang, Peng and Wang, Shijie and Tang, Jun and Zhong, Humen and Zhu, Yuanzhi and Yang, Mingkun and Li, Zhaohai and Wan, Jianqiang and Wang, Pengfei and Ding, Wei and Fu, Zheren and Xu, Yiheng and Ye, Jiabo and Zhang, Xi and Xie, Tianbao and Cheng, Zesen and Zhang, Hang and Yang, Zhibo and Xu, Haiyang and Lin, Junyang},
  journal={arXiv preprint arXiv:2502.13923},
  year={2025}
}

@article{Qwen2VL,
  title={Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution},
  author={Wang, Peng and Bai, Shuai and Tan, Sinan and Wang, Shijie and Fan, Zhihao and Bai, Jinze and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Fan, Yang and Dang, Kai and Du, Mengfei and Ren, Xuancheng and Men, Rui and Liu, Dayiheng and Zhou, Chang and Zhou, Jingren and Lin, Junyang},
  journal={arXiv preprint arXiv:2409.12191},
  year={2024}
}

@article{Qwen-VL,
  title={Qwen-VL: A Versatile Vision-Language Model for Understanding, Localization, Text Reading, and Beyond},
  author={Bai, Jinze and Bai, Shuai and Yang, Shusheng and Wang, Shijie and Tan, Sinan and Wang, Peng and Lin, Junyang and Zhou, Chang and Zhou, Jingren},
  journal={arXiv preprint arXiv:2308.12966},
  year={2023}
}

Configuration

Architecture
Qwen3VLForConditionalGeneration
Context length (tokens)
262,144
Layers
36
Hidden size
4,096
Feed-forward size
12,288
Attention heads
32
Key/value heads
8
Head dimension
128
Vocabulary size
151,936
RoPE base
5,000,000
Model type
qwen3_vl
Quantization
fp8

Identity and Version

Repository
Qwen/Qwen3-VL-8B-Instruct-FP8
Publisher
Qwen
Task
Image and text to text
Modality
Image and text
Library
transformers
Parameters
8.8B parameters
Languages
Not stated by the source
Revision
9cdc6310a8cb770ce18efaf4e9935334512aee45
First published
2025-10-11
Last updated
2025-11-26

Files and Weights

13 files, 10.6 GB in total. The weights are 2 files totalling 10.6 GB in safetensors.

Weights2 files · 10.6 GB
Configuration6 files · 112.9 KB
Tokenizer3 files · 15.1 MB
Documentation1 file · 10.4 KB
Repository1 file · 1.5 KB
Every file
FileTypeSizeSHA-256
model-00001-of-00002.safetensorsWeights5.4 GB e2dea2e85e64
model-00002-of-00002.safetensorsWeights5.2 GB 3dc64ec934af
chat_template.jsonConfiguration5.5 KB
config.jsonConfiguration12.0 KB
generation_config.jsonConfiguration241 B
model.safetensors.index.jsonConfiguration94.5 KB
preprocessor_config.jsonConfiguration336 B
video_preprocessor_config.jsonConfiguration331 B
README.mdDocumentation10.4 KB
.gitattributesRepository1.5 KB
tokenizer.jsonTokenizer10.2 MB
tokenizer_config.jsonTokenizer10.9 KB
vocab.jsonTokenizer5.0 MB

License and Download

License
apache-2.0
Access
Open weights, no gate
Download size
10.6 GB
Download from Qwen

Released by Qwen through ModelScope. Read the license.

Built From

Memory Requirements

PrecisionWeights in memory
As published10.6 GB
16-bit17.5 GB
8-bit8.8 GB
4-bit4.4 GB

Weights only, from the published parameter count; the key-value cache and runtime add to this.

Questions About Qwen3-VL-8B-Instruct-FP8

How much GPU memory does Qwen3-VL-8B-Instruct-FP8 need?

About 21 GB at 16-bit and 5.3 GB at 4-bit: the weights (8.8B parameters) plus a working margin. A long context needs more.

What is the cheapest GPU to run Qwen3-VL-8B-Instruct-FP8 on?

At 16-bit, 1x MI300X from $1.85 an hour; at 4-bit, 1x MI300X from $1.85 an hour, at the lowest on-demand prices the SAVRN Index lists.

Can I use Qwen3-VL-8B-Instruct-FP8 commercially?

Yes. Qwen3-VL-8B-Instruct-FP8 is released under Apache License 2.0. The Apache License 2.0 is a permissive open-source license. It permits commercial use, modification and redistribution. It requires keeping the license and copyright notices and any NOTICE file, stating significant changes, and it includes an express patent grant from contributors.

What is Qwen3-VL-8B-Instruct-FP8's context length?

262,144 tokens, from the maximum position embeddings in its published configuration.

Similar Models

Model · Image and text to text

Qwen3-VL-8B-Instruct

Qwen

Meet Qwen3-VL — the most powerful vision-language model in the Qwen series to date. This generation delivers comprehensive upgrades across the board: superior text understanding & generation, deeper visual perception & reasoning, extended context length, enhanced spatial and video dynamics comprehension, and stronger agent interaction capabilities. Available in Dense and MoE architectures that scale from edge to cloud, with Instruct and reasoning‑enhanced Thinking editions for flexible, on‑demand deployment. Text Understanding on par with pure LLMs: Seamless text–vision fusion for lossless, unified comprehension. 1. Interleaved-MRoPE: Full‑frequency allocation over time, width, and height…

Open weights apache-2.0 8.8B parameters 262,144 tokens transformers

Model · Image and text to text

MemGUI-8B-RL

Anonymous

Anonymous release for the ICLR 2027 submission MemGUI-RL: Reinforcement Learning for Proactive Context Management in Long-Horizon Mobile GUI Agents. Project page: https://memgui-rl-anonymous.github.io/ MemGUI-8B-RL is MemGUI-8B-SFT (Qwen3-VL-8B-Instruct supervised on MemGUI-3K) post-trained for 100 optimizer steps with FARPO (Folding-Aware Reward-decoupled Policy Optimization, span-to-step ratio rho = 9). The policy speaks the ConAct (Context-as-Action) interface of MemGUI-Agent: every response contains a folding directive for its own history, an optional memory operation and the next GUI action. The checkpoint is a standard Qwen3VLForConditionalGeneration model (weights in bf16, ~17.5 GB).…

Open weights apache-2.0 8.8B parameters 262,144 tokens

Model · Image and text to text

Qwen2.5-VL-7B-Instruct

Qwen

pipelinetag: image-text-to-text - multimodal libraryname: transformers In the past five months since Qwen2-VL’s release, numerous developers have built new models on the Qwen2-VL vision-language models, providing us with valuable feedback. During this period, we focused on building more useful vision-language models. Today, we are excited to introduce the latest addition to the Qwen family: Qwen2.5-VL. Understanding long videos and capturing events: Qwen2.5-VL can comprehend videos of over 1 hour, and this time it has a new ability of cpaturing event by pinpointing the relevant video segments. Capable of visual localization in different formats: Qwen2.5-VL can accurately localize objects in…

Open weights apache-2.0 8.3B parameters 128,000 tokens transformers

Model · Image and text to text

Qwen2.5-VL-7B-Instruct-AWQ

Qwen

In the past five months since Qwen2-VL’s release, numerous developers have built new models on the Qwen2-VL vision-language models, providing us with valuable feedback. During this period, we focused on building more useful vision-language models. Today, we are excited to introduce the latest addition to the Qwen family: Qwen2.5-VL. Understanding long videos and capturing events: Qwen2.5-VL can comprehend videos of over 1 hour, and this time it has a new ability of cpaturing event by pinpointing the relevant video segments. Capable of visual localization in different formats: Qwen2.5-VL can accurately localize objects in an image by generating bounding boxes or points, and it can provide…

Open weights apache-2.0 8.3B parameters 128,000 tokens transformers

Model · Image and text to text

Qwen2-VL-7B-Instruct-AWQ

Qwen

We're excited to unveil Qwen2-VL, the latest iteration of our Qwen-VL model, representing nearly a year of innovation. SoTA understanding of images of various resolution & ratio: Qwen2-VL achieves state-of-the-art performance on visual understanding benchmarks, including MathVista, DocVQA, RealWorldQA, MTVQA, etc. Understanding videos of 20min+: Qwen2-VL can understand videos over 20 minutes for high-quality video-based question answering, dialog, content creation, etc. Agent that can operate your mobiles, robots, etc.: with the abilities of complex reasoning and decision making, Qwen2-VL can be integrated with devices like mobile phones, robots, etc., for automatic operation based on…

Open weights apache-2.0 8.3B parameters 32,768 tokens transformers

Model · Image and text to text

Qwen2-VL-7B-Instruct

Qwen

We're excited to unveil Qwen2-VL, the latest iteration of our Qwen-VL model, representing nearly a year of innovation. SoTA understanding of images of various resolution & ratio: Qwen2-VL achieves state-of-the-art performance on visual understanding benchmarks, including MathVista, DocVQA, RealWorldQA, MTVQA, etc. Understanding videos of 20min+: Qwen2-VL can understand videos over 20 minutes for high-quality video-based question answering, dialog, content creation, etc. Agent that can operate your mobiles, robots, etc.: with the abilities of complex reasoning and decision making, Qwen2-VL can be integrated with devices like mobile phones, robots, etc., for automatic operation based on…

Open weights apache-2.0 8.3B parameters 32,768 tokens transformers