SAVRN
Search Contact SAVRN

Open-weight model · Text to image

lcm-lora-sdv1-5

by Latent Consistency latent-consistency/lcm-lora-sdv1-5

Latent Consistency Model (LCM) LoRA was proposed in LCM-LoRA: A universal Stable-Diffusion Acceleration Module by Simian Luo, Yiqin Tan, Suraj Patil, Daniel Gu et al.

Parameters
Context
Weights134.6 MB
Licenseopenrail++
AccessOpen weights
Monthly Downloads93.2k

Model Card

By Latent Consistency, published under openrail++, revision cf2fced511db.

Latent Consistency Model (LCM) LoRA was proposed in LCM-LoRA: A universal Stable-Diffusion Acceleration Module by Simian Luo, Yiqin Tan, Suraj Patil, Daniel Gu et al. It is a distilled consistency adapter for runwayml/stable-diffusion-v1-5 that allows to reduce the number of inference steps to only between 2 - 8 steps. LCM-LoRA is supported in Hugging Face Diffusers library from version v0.23.0 onwards. To run the model, first install the latest version of the Diffusers library as well as peft, accelerate and transformers. audio dataset from the Hugging Face Hub: Note: For detailed usage examples we recommend you to check out our official LCM-LoRA docs The adapter can be loaded with SDv1-5…

Read Latent Consistency's full model card

Latent Consistency Model (LCM) LoRA: SDv1-5

Latent Consistency Model (LCM) LoRA was proposed in LCM-LoRA: A universal Stable-Diffusion Acceleration Module by Simian Luo, Yiqin Tan, Suraj Patil, Daniel Gu et al.

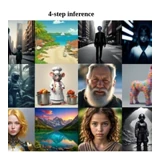
It is a distilled consistency adapter for runwayml/stable-diffusion-v1-5 that allows to reduce the number of inference steps to only between 2 - 8 steps.

Model Params / M
lcm-lora-sdv1-5 67.5
lcm-lora-ssd-1b 105
lcm-lora-sdxl 197M

Usage

LCM-LoRA is supported in Hugging Face Diffusers library from version v0.23.0 onwards. To run the model, first install the latest version of the Diffusers library as well aspeft, accelerate and transformers. audio dataset from the Hugging Face Hub:

pip install --upgrade pip
pip install --upgrade diffusers transformers accelerate peft

Note: For detailed usage examples we recommend you to check out our official LCM-LoRA docs

Text-to-Image

The adapter can be loaded with SDv1-5 or deviratives. Here we use Lykon/dreamshaper-7. Next, the scheduler needs to be changed to LCMScheduler and we can reduce the number of inference steps to just 2 to 8 steps. Please make sure to either disable guidance_scale or use values between 1.0 and 2.0.

import torch
from diffusers import LCMScheduler, AutoPipelineForText2Image

model_id = "Lykon/dreamshaper-7"
adapter_id = "latent-consistency/lcm-lora-sdv1-5"

pipe = AutoPipelineForText2Image.from_pretrained(model_id, torch_dtype=torch.float16, variant="fp16")
pipe.scheduler = LCMScheduler.from_config(pipe.scheduler.config)
pipe.to("cuda")

# load and fuse lcm lora
pipe.load_lora_weights(adapter_id)
pipe.fuse_lora()


prompt = "Self-portrait oil painting, a beautiful cyborg with golden hair, 8k"

# disable guidance_scale by passing 0
image = pipe(prompt=prompt, num_inference_steps=4, guidance_scale=0).images[0]

Image-to-Image

LCM-LoRA can be applied to image-to-image tasks too. Let's look at how we can perform image-to-image generation with LCMs. For this example we'll use the dreamshaper-7 model and the LCM-LoRA for stable-diffusion-v1-5.

import torch
from diffusers import AutoPipelineForImage2Image, LCMScheduler
from diffusers.utils import make_image_grid, load_image

pipe = AutoPipelineForImage2Image.from_pretrained(
    "Lykon/dreamshaper-7",
    torch_dtype=torch.float16,
    variant="fp16",
).to("cuda")

# set scheduler
pipe.scheduler = LCMScheduler.from_config(pipe.scheduler.config)

# load LCM-LoRA
pipe.load_lora_weights("latent-consistency/lcm-lora-sdv1-5")
pipe.fuse_lora()

# prepare image
url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/img2img-init.png"
init_image = load_image(url)
prompt = "Astronauts in a jungle, cold color palette, muted colors, detailed, 8k"

# pass prompt and image to pipeline
generator = torch.manual_seed(0)
image = pipe(
    prompt,
    image=init_image,
    num_inference_steps=4,
    guidance_scale=1,
    strength=0.6,
    generator=generator
).images[0]
make_image_grid([init_image, image], rows=1, cols=2)

Inpainting

LCM-LoRA can be used for inpainting as well.

import torch
from diffusers import AutoPipelineForInpainting, LCMScheduler
from diffusers.utils import load_image, make_image_grid

pipe = AutoPipelineForInpainting.from_pretrained(
    "runwayml/stable-diffusion-inpainting",
    torch_dtype=torch.float16,
    variant="fp16",
).to("cuda")

# set scheduler
pipe.scheduler = LCMScheduler.from_config(pipe.scheduler.config)

# load LCM-LoRA
pipe.load_lora_weights("latent-consistency/lcm-lora-sdv1-5")
pipe.fuse_lora()

# load base and mask image
init_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/inpaint.png")
mask_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/inpaint_mask.png")

# generator = torch.Generator("cuda").manual_seed(92)
prompt = "concept art digital painting of an elven castle, inspired by lord of the rings, highly detailed, 8k"
generator = torch.manual_seed(0)
image = pipe(
    prompt=prompt,
    image=init_image,
    mask_image=mask_image,
    generator=generator,
    num_inference_steps=4,
    guidance_scale=4, 
).images[0]
make_image_grid([init_image, mask_image, image], rows=1, cols=3)

ControlNet

For this example, we'll use the SD-v1-5 model and the LCM-LoRA for SD-v1-5 with canny ControlNet.

import torch
import cv2
import numpy as np
from PIL import Image

from diffusers import StableDiffusionControlNetPipeline, ControlNetModel, LCMScheduler
from diffusers.utils import load_image

image = load_image(
    "https://hf.co/datasets/huggingface/documentation-images/resolve/main/diffusers/input_image_vermeer.png"
).resize((512, 512))

image = np.array(image)

low_threshold = 100
high_threshold = 200

image = cv2.Canny(image, low_threshold, high_threshold)
image = image[:, :, None]
image = np.concatenate([image, image, image], axis=2)
canny_image = Image.fromarray(image)

controlnet = ControlNetModel.from_pretrained("lllyasviel/sd-controlnet-canny", torch_dtype=torch.float16)
pipe = StableDiffusionControlNetPipeline.from_pretrained(
    "runwayml/stable-diffusion-v1-5",
    controlnet=controlnet,
    torch_dtype=torch.float16,
    safety_checker=None,
    variant="fp16"
).to("cuda")

# set scheduler
pipe.scheduler = LCMScheduler.from_config(pipe.scheduler.config)

# load LCM-LoRA
pipe.load_lora_weights("latent-consistency/lcm-lora-sdv1-5")

generator = torch.manual_seed(0)
image = pipe(
    "the mona lisa",
    image=canny_image,
    num_inference_steps=4,
    guidance_scale=1.5,
    controlnet_conditioning_scale=0.8,
    cross_attention_kwargs={"scale": 1},
    generator=generator,
).images[0]
make_image_grid([canny_image, image], rows=1, cols=2)

Speed Benchmark

TODO

Training

TODO
Identity and Version

Repository
latent-consistency/lcm-lora-sdv1-5
Publisher
Latent Consistency
Task
Text to image
Modality
Image
Library
diffusers
Parameters
Not stated by the source
Languages
Not stated by the source
Revision
cf2fced511dbe7e26c8d1d397e728fbab875db4b
First published
2023-11-07
Last updated
2023-11-16

Files and Weights

4 files, 135.0 MB in total. The weights are 1 file totalling 134.6 MB in safetensors.

Weights1 file · 134.6 MB
Documentation1 file · 7.2 KB
Other1 file · 390.4 KB
Repository1 file · 1.5 KB
Every file
FileTypeSizeSHA-256
pytorch_lora_weights.safetensorsWeights134.6 MB 8f90d840e075
README.mdDocumentation7.2 KB
image.pngOther390.4 KB
.gitattributesRepository1.5 KB

License and Download

License
openrail++
Access
Open weights, no gate
Download size
134.6 MB
Download from Latent Consistency

Released by Latent Consistency through its official repository on Hugging Face.

Built From

  • Adapter of runwayml/stable-diffusion-v1-5
  • Derived from runwayml/stable-diffusion-v1-5
  • Described by arXiv:2311.05556

Memory Requirements

PrecisionWeights in memory
As published134.6 MB

Weights only, from the published parameter count; the key-value cache and runtime add to this.

Questions About lcm-lora-sdv1-5

Can I use lcm-lora-sdv1-5 commercially?

Yes, with conditions. lcm-lora-sdv1-5 is released under Open RAIL++ License. Open RAIL++ permits use, including commercial use, subject to the use-based restrictions listed in the license, which must be passed on to downstream users.

Similar Models

Model · Text to image

Juggernaut-XL-v9

RunDiffusion

The SDXL ecosystem is the single most mature corner of open image generation, and v9 is its most refined photorealism checkpoint. Choose Juggernaut XL v9 when you want: - Photorealism that holds up under scrutiny — skin texture, micro-contrast, and natural lighting that translates from concept to print. - Reasonable hardware — runs comfortably on 8 GB of VRAM, unlike newer DiT-based models that demand 16+ GB. - The full SDXL toolbox — drop-in compatibility with the thousands of SDXL ControlNets, IP-Adapter variants, AnimateDiff, regional prompting tools, and LoRAs already in your workflow. - Battle-tested reliability — 26+ months in production, used in agencies, studios, and shipping…

Open weights creativeml-openrail-m diffusers

Model · Text to image

Qwen-Image-Lightning

Lightx2v

Please refer to Qwen-Image-Lightning github to learn how to use the models. make sure to install diffusers from main (pip install git+https://github.com/huggingface/diffusers.git)

Open weights apache-2.0 diffusers

Model · Text to image

Z-Image-Lora

nphSi

+ Always use full LoRa name with "vrtlxxxx" trigger in prompt like "Alba Baptista (vrtlalbabaptista) in a swimming pool". "Woman" or "1girl" will NOT work due to my way i do captions. + Add the gender to the prompt for confusing names like "Alex Jones". + Remove the name when internal model knowledge is bad or censored or is confusing to model like "Sandy Cheeks" or "Kate Middleton". + When using a Lora with multiple triggers (vrtlxx,vrtlyy) do not use the real character name but only trigger or a combination of it. "vrtlMain" always combines all trigger-words. Angourie Rice, January Jones, Julianna Guill, Ursula Corbero, Judith Rakers, Alina Merkau, Kiernan Shipka, Leslie Bibb, Marie…

Open weights apache-2.0 diffusers

Model · Text to image

Flux2-Klein-9B-True-V2

Wikee Yang

Recommend smthemex/ComfyUIUniBlockSwap plugin for LOW VRAM users, it only requires 4-6GB of VRAM to run the full bf16 model. 您可以尝试一下全新的 ComfyUI GGUF 模型加载插件 smthemex/ComfyUIDifGGUF,它能适配更多的 GGUF 文件格式,并且将很快集成低显存(4-8GB)显卡的 GGUF 模型块卸载管理能力。 Recommend to try the new GGUF ComfyUI loader plugin, smthemex/ComfyUIDifGGUF, it compatible with more GGUF format, and will add low VRAM (4-8GB) management for GGUF soon. 1. 图像的真实感和质感进一步改善,基本接近香蕉(Nano Banana)的水平。 2. 提示词遵循和还原能力,参数适配性和LoRA兼容性进一步改善,。 The V2 version of this model has undergone a full fine-tuning based on FLUX.2-Klein-9B-True-V1. Compared to the V1 version, it has some improvements and enhancements as below: 1. The realism and texture of images…

Open weights other diffusers

Model · Text to image

Z-Image-Turbo-GGUF

Unsloth AI

Welcome to the official repository for the Z-Image(造相)project! Z-Image is a powerful and highly efficient image generation model with 6B parameters. Currently there are three variants: - Z-Image-Turbo – A distilled version of Z-Image that matches or exceeds leading competitors with only 8 NFEs (Number of Function Evaluations). It offers sub-second inference latency on enterprise-grade H800 GPUs and fits comfortably within 16G VRAM consumer devices. It excels in photorealistic image generation, bilingual text rendering (English & Chinese), and robust instruction adherence. - Z-Image-Base – The non-distilled foundation model. By releasing this checkpoint, we aim to unlock the full potential…

Open weights apache-2.0 ggml

Model · Text to image

FLUX.1-dev-gguf

City

This is a direct GGUF conversion of black-forest-labs/FLUX.1-dev As this is a quantized model not a finetune, all the same restrictions/original license terms still apply. The model files can be used with the ComfyUI-GGUF custom node. Place model files in ComfyUI/models/unet - see the GitHub readme for further install instructions. Please refer to this chart for a basic overview of quantization types.

Open weights other gguf