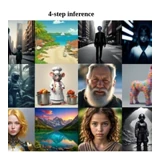
SDXL consists of an ensemble of experts pipeline for latent diffusion: In a first step, the base model is used to generate (noisy) latents, which are then further processed with a refinement model (available here: https://huggingface.co/stabilityai/stable-diffusion-xl-refiner-1.0/) specialized for the final denoising steps. Note that the base model can be used as a standalone module. Alternatively, we can use a two-stage pipeline as follows: First, the base model is used to generate latents of the desired output size. In the second step, we use a specialized high-resolution model and apply a technique called SDEdit (https://arxiv.org/abs/2108.01073, also known as "img2img") to the latents…
Open weights
openrail++
2.6B parameters
diffusers
Animagine XL 4.0, also stylized as Anim4gine, is the ultimate anime-themed finetuned SDXL model and the latest installment of Animagine XL series. Despite being a continuation, the model was retrained from Stable Diffusion XL 1.0 with a massive dataset of 8.4M diverse anime-style images from various sources with the knowledge cut-off of January 7th 2025 and finetuned for approximately 2650 GPU hours. Similar to the previous version, this model was trained using tag ordering method for the identity and style training. With the release of Animagine XL 4.0 Opt (Optimized), the model has been further refined with an additional dataset, improving stability, anatomy accuracy, noise reduction…
Open weights
openrail++
2.6B parameters
diffusers
/ FIXED: Changed from 50% to 33.33% because there are 3 columns / margin-bottom: 1em; / Added small margin for spacing between stacked images / font-weight: bold; / Corrected 'font-style: bold' to 'font-weight: bold' / } / FIXED: Added missing closing brace here /.overlay, Animagine XL 3.1 is an update in the Animagine XL V3 series, enhancing the previous version, Animagine XL 3.0. This open-source, anime-themed text-to-image model has been improved for generating anime-style images with higher quality. It includes a broader range of characters from well-known anime series, an optimized dataset, and new aesthetic tags for better image creation. Built on Stable Diffusion XL, Animagine XL 3.1…
Open weights
openrail++
2.6B parameters
diffusers
basemodel: stabilityai/stable-diffusion-xl-base-1.0 - stable-diffusion-xl - stable-diffusion-xl-diffusers - text-to-image - diffusers - inpainting SD-XL Inpainting 0.1 is a latent text-to-image diffusion model capable of generating photo-realistic images given any text input, with the extra capability of inpainting the pictures by using a mask. The SD-XL Inpainting 0.1 was initialized with the stable-diffusion-xl-base-1.0 weights. The model is trained for 40k steps at resolution 1024x1024 and 5% dropping of the text-conditioning to improve classifier-free classifier-free guidance sampling. For inpainting, the UNet has 5 additional input channels (4 for the encoded masked-image and 1 for the…
Open weights
openrail++
2.6B parameters
diffusers
Model · Text classification
S NLP
This model is trained for toxicity classification task. The dataset used for training is the merge of the English parts of the three datasets by Jigsaw (Jigsaw 2018, Jigsaw 2019, Jigsaw 2020), containing around 2 million examples. We split it into two parts and fine-tune a RoBERTa model (RoBERTa: A Robustly Optimized BERT Pretraining Approach) on it. The classifiers perform closely on the test set of the first Jigsaw competition, reaching the AUC-ROC of 0.98 and F1-score of 0.76. To acknowledge our work, please, use the corresponding citation: This model is licensed under the OpenRAIL++ License, which supports the development of various technologies—both industrial and academic—that serve…
Open weights
openrail++
514 tokens
transformers
A LoRA adapter for the Qwen-Image-Edit-2511 diffusion pipeline, enabling NSFW content generation and editing capabilities. The easiest way to use this LoRA is through the ScottzillaSystems Image Editor — select " MCNL-NSFW-v1" from the adapter dropdown. Use these concepts in your prompts to activate specific capabilities: nsfw nipples vagina penis missionary cowgirlout reversecowgirlpov blowjob cumonface creamp1e l1ck
Open weights
openrail++
diffusers
Latent Consistency Model (LCM) LoRA was proposed in LCM-LoRA: A universal Stable-Diffusion Acceleration Module by Simian Luo, Yiqin Tan, Suraj Patil, Daniel Gu et al. It is a distilled consistency adapter for runwayml/stable-diffusion-v1-5 that allows to reduce the number of inference steps to only between 2 - 8 steps. LCM-LoRA is supported in Hugging Face Diffusers library from version v0.23.0 onwards. To run the model, first install the latest version of the Diffusers library as well as peft, accelerate and transformers. audio dataset from the Hugging Face Hub: Note: For detailed usage examples we recommend you to check out our official LCM-LoRA docs The adapter can be loaded with SDv1-5…
Open weights
openrail++
diffusers
SDXL-Lightning is a lightning-fast text-to-image generation model. It can generate high-quality 1024px images in a few steps. For more information, please refer to our research paper: SDXL-Lightning: Progressive Adversarial Diffusion Distillation. We open-source the model as part of the research. Our models are distilled from stabilityai/stable-diffusion-xl-base-1.0. This repository contains checkpoints for 1-step, 2-step, 4-step, and 8-step distilled models. The generation quality of our 2-step, 4-step, and 8-step model is amazing. Our 1-step model is more experimental. We provide both full UNet and LoRA checkpoints. The full UNet models have the best quality while the LoRA models can be…
Open weights
openrail++
diffusers
You should use Lisa to trigger the image generation. You should use Curly black hair to trigger the image generation. You should use Long eyelashes to trigger the image generation. You should use Medium skin to trigger the image generation. Download them in the Files & versions tab.
Open weights
openrail++
diffusers